A sparse reward gives feedback at only a few points in a multi-step task, often only at the end. The agent must learn from outcomes rather than feedback at every decision. section 2.6.1 section 10.3
Reward timing is a design choice. Delivery fuel costs might be measured only after a route, while daily stock rewards or penalties provide intermediate guidance. When direct feedback is delayed, measures such as clicks or engagement can serve as approximations. section 2.6.1
Figure 10.2 Language generation mapped as a Markov Decision Process.
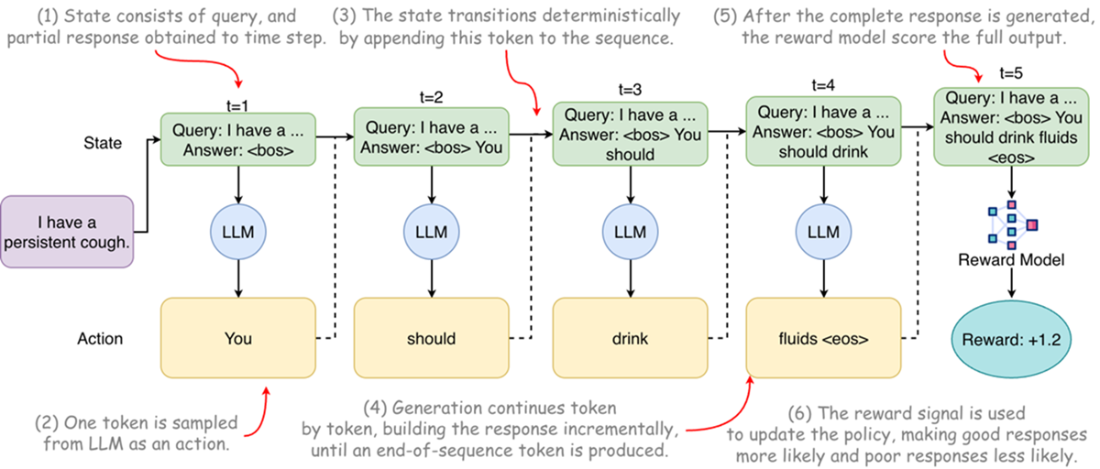
Language generation extends the state with each token, then provides one reward after the complete response. section 10.3
