The evidence lower bound (ELBO) is an easily computed objective for training a variational Gaussian process (VGP) when the marginal log likelihood and KL divergence are difficult to compute. It equals the marginal log likelihood minus the KL divergence, so maximizing it indirectly maximizes the marginal log likelihood while encouraging the approximate posterior to resemble the full-data posterior. section 12.2.1 section 12.5
A practical ELBO training workflow is:
- Represent the large dataset with inducing points and optimize their locations so the VGP approximates a GP trained on all data. section 12.2.1 section 12.2.3
- Estimate the loss on small data batches, whose repeated updates provide a stable approximation to the loss over the full dataset. section 12.2.2
- Use mini-batch gradient descent for regular parameters and natural gradient descent when optimizing variational parameters. section 12.5
Training a VGP with GPyTorch
In GPyTorch, construct a VariationalELBO with the likelihood, model, and total data count. For each batch, compute output = model(x_batch), set loss = -mll(output, y_batch), backpropagate, and update the model and likelihood parameters. After training, switch both to evaluation mode. The negative sign converts ELBO maximization into loss minimization. section 12.2.3
Figure 12.8 The KL divergence is decomposed into the difference between the marginal log likelihood and the evidence lower bound (ELBO). The ELBO is easy to compute and, therefore, chosen as the metric to be optimized.
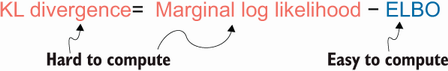
The decomposition diagram connects the KL divergence, marginal log likelihood, and ELBO, showing why the ELBO is selected as the optimization metric. section 12.2.1



