FAISS is an open-source library for storing embeddings and performing fast, scalable similarity searches across large datasets. It provides a vector-database alternative to ChromaDB in retrieval-augmented generation (RAG) systems. section 6.3
A practical FAISS workflow uses these stages:
- Split source material into meaningful chunks, such as one recipe per chunk. section 6.3
- Connect the chunks to an embedding model, such as OpenAI Embeddings, so they become numbers. section 6.3
- Send the embeddings to FAISS, choose an index name, and run the component to create the index directory. section 6.3
Recipe retrieval
A HealthyChef workflow stores Italian recipe chunks in a FAISS index named cookbook, making the recipe collection available to an agent. section 6.3
Figure 6.8 In the first part of our flow, we created a vector database packed with Italian recipes.
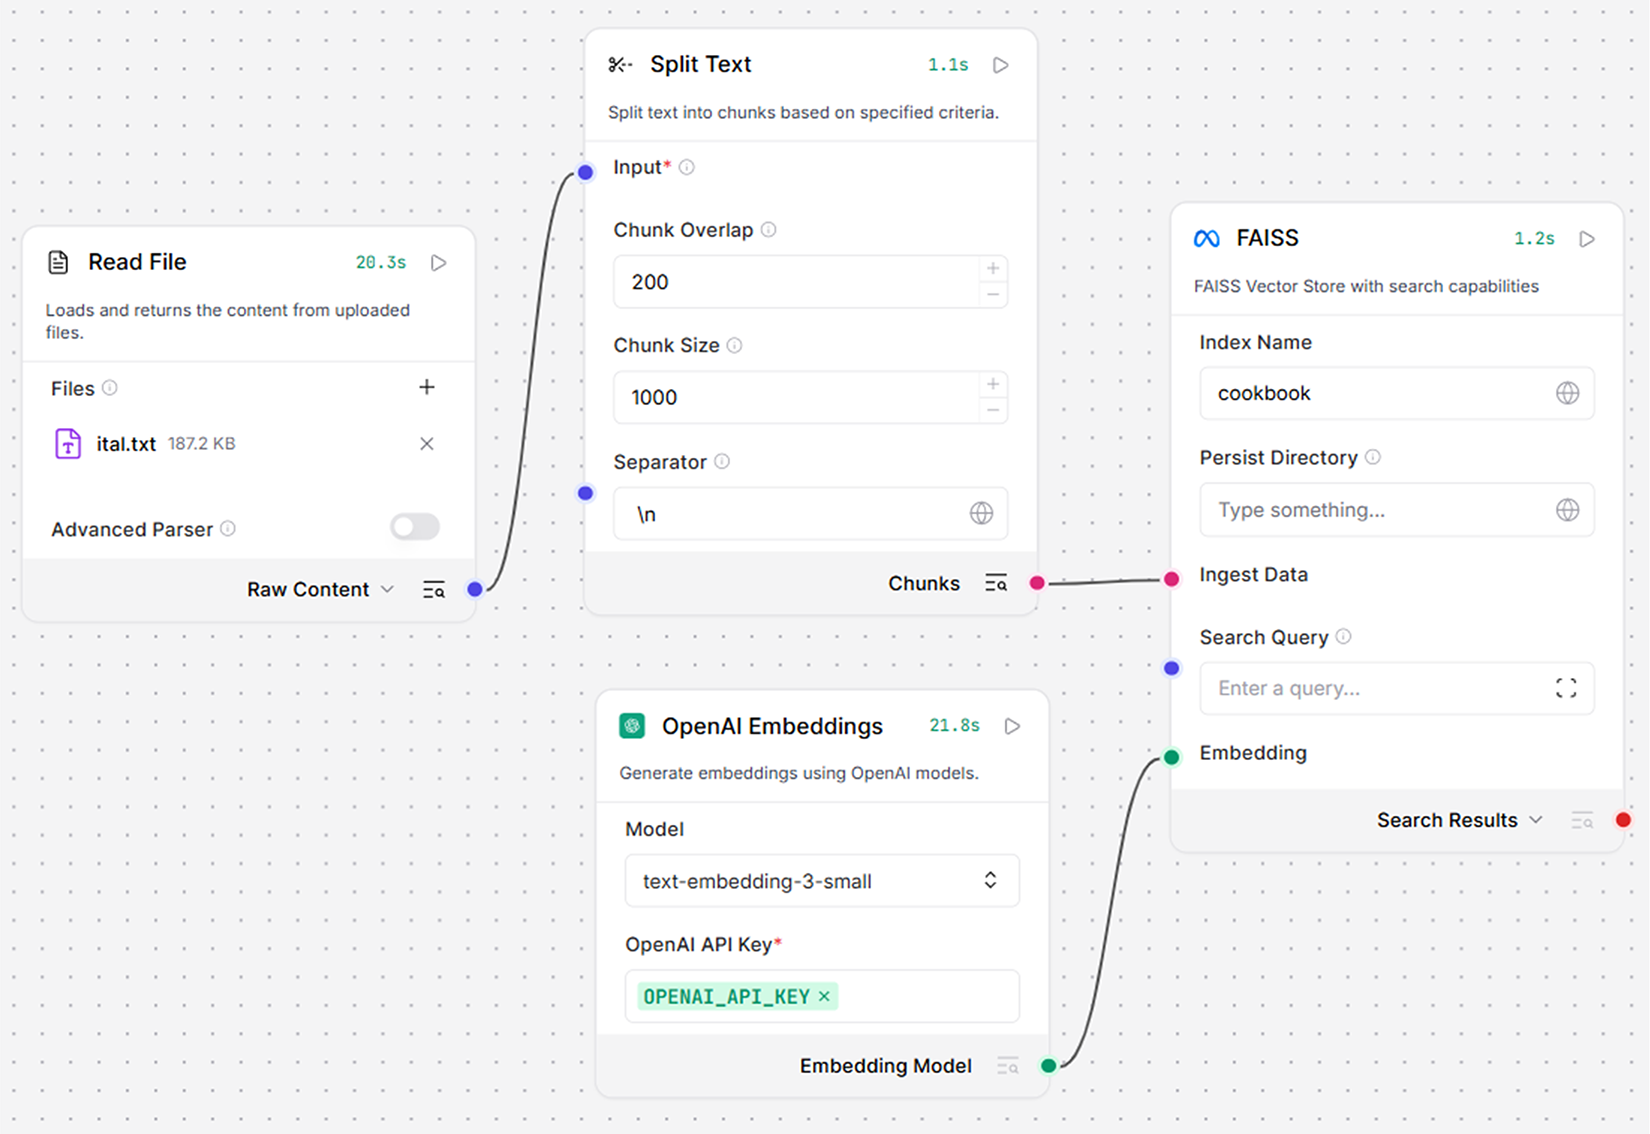
Shows the flow that creates a vector database packed with Italian recipes. section 6.3



