Formatting transforms imported data into a structure and value types that a visualization can use. In D3, the row conversion callback is a practical place to reshape each CSV row before the dataset is fully loaded. section 3.2.2
A useful formatting workflow includes these decisions:
- Inspect imported rows first; CSV counts commonly arrive as strings because the data has been converted from CSV to JSON. section 3.2.2
- Convert values needed for visualization, such as turning d.count into a number with the unary + operator. section 3.2.2
- Return only the key-value pairs required later, or format the complete dataset afterward when many columns must remain. section 3.2.2
- Gather, analyze, clean, and format data when ready-to-use datasets are unavailable; this preparation can require substantial time and diligence. section 14.1
Convert a CSV row for D3
d3.csv("../data/data.csv", d => { return { technology: d.technology, count: +d.count }; }); The returned object preserves technology and exposes count as a number. Only these returned properties remain available once the dataset finishes loading. section 3.2.2
Figure 3.9 The third step of the D3 data workflow consists initially of formatting the data so that it’s ready to use when you start building your visualization.
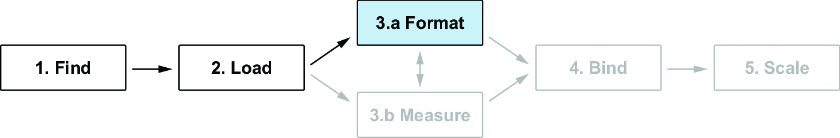
Use the data-workflow diagram to place formatting between importing data and building the visualization. section 3.2.2






