GPU video memory, usually called VRAM, is the memory a graphics processor uses while generating images. It is the practical ceiling behind many “why won’t this run?” moments: generating more images at once, using more pixels, or loading a larger model all demand more of it. section 1.2.2 section 7.1.2
Batch size spends VRAM by generating several images simultaneously on the GPU. Batch count instead runs generations sequentially, so it can produce the same total number of images with a smaller memory demand. A larger batch is not guaranteed to save much time, so test combinations that suit the hardware rather than treating parallelism as free speed. section 1.2.2
Figure 1.5 Batch count and Batch size theoretically offer different ways to increase images generated
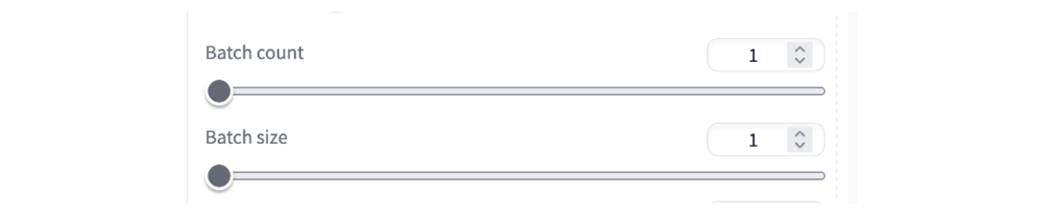
Compare batch size with batch count before raising either setting: both increase total output, but only batch size puts multiple images in the same GPU workload. section 1.2.2
Image dimensions are another fast way to fill VRAM. More total pixels from width × height require more memory, so use dimensions primarily to choose an aspect ratio instead of trying to generate final high resolution directly. If the allocation exceeds available memory, generation can fail with “CUDA out of memory.” Even hardware able to make a 2048×2048 image may produce poor results because the model was trained at much smaller sizes. section 1.2.4 section 7.1.2
When VRAM is tight, change the workload before declaring defeat:
- Lower batch size and use a higher batch count to create images sequentially. section 1.2.2
- Reduce width and height while preserving the aspect ratio you need. section 1.2.4
- Use smaller or quantized model files when a large model will not fit on consumer hardware. section 10.1.2 section 11.1
Inference versus fine-tuning
Memory needs change dramatically with the job. Flux inference at full precision takes around 24GB of VRAM, while quantization can reduce that to roughly 8–12GB. Fine-tuning needs substantially more memory because training repeatedly updates weights and tracks additional information; even optimized Flux training is estimated at 80–150GB. section 11.1