GPT-4 is a large GPT language model for processing text, including tasks such as classifying reviews and writing complex data-processing code. Its stronger capabilities come with substantially higher per-token costs, so model choice should match the task. section 1.5.1 section 9.1
Use GPT-4 selectively when evaluating language-model options:
- Choose it when a task requires complex code or higher-quality text processing than a smaller model provides. section 1.5.1
- Compare quality against token costs rather than treating the largest model as the automatic default. section 1.5.1 section 9.4
- Test candidate models on representative task data, using benchmarks such as HELM as an initial comparison point. section 1.5.1 section 9.4
Classifying product reviews
A review-classification prompt can provide GPT-4 with one review, instructions, and labels such as “positive” and “negative.” In a comparison with GPT-3.5 Turbo, GPT-4 solved one additional test case accurately, reaching 80% accuracy, but cost roughly 120 times more because of its higher per-token fees. section 9.1 section 9.4
Figure 1.4 Holistic Evaluation of Language Models (HELM): comparing language models offered by different providers according to various metrics
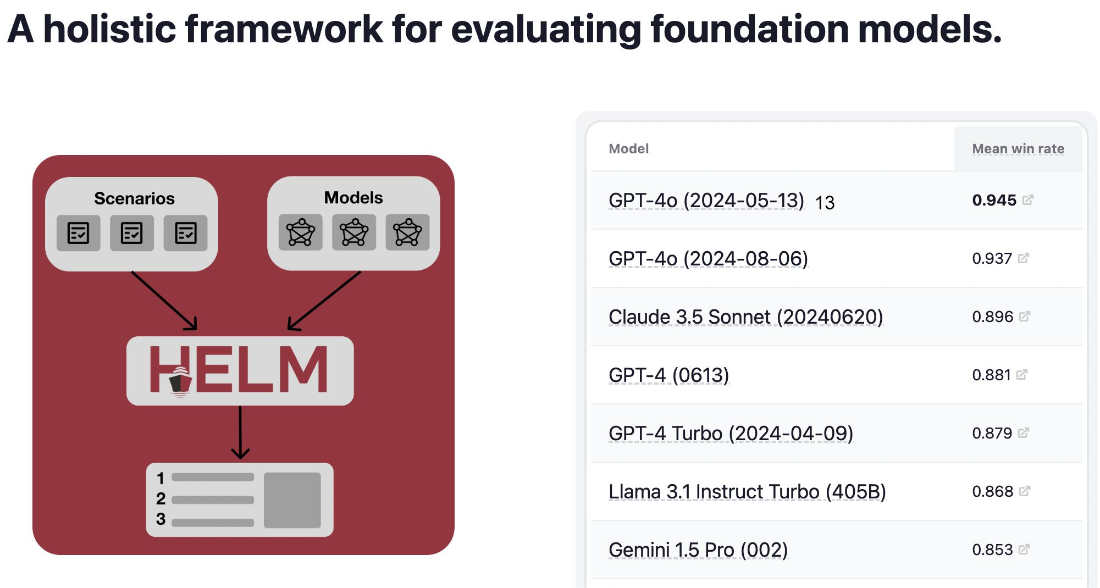
Compare language models from different providers across task metrics with the HELM benchmark. section 1.5.1




