Grouped-query attention (GQA) reduces key-value (KV) cache memory by partitioning query heads into groups. Heads in a group share key and value projections; different groups retain distinct projections. It offers a tunable compromise between the expressivity of multi-head attention (MHA) and the memory efficiency of multi-query attention (MQA). section 2.7 section 2.7.1
Figure 2.25 Grouped-Query Attention (GQA). The four attention heads are divided into two groups. Within Group 1 (light blue/light yellow), Head 1 and Head 2 share the same Key and Value projections. Within Group 2 (dark blue/dark yellow), Head 3 and Head 4 share a different, distinct set of Key and Value projections.
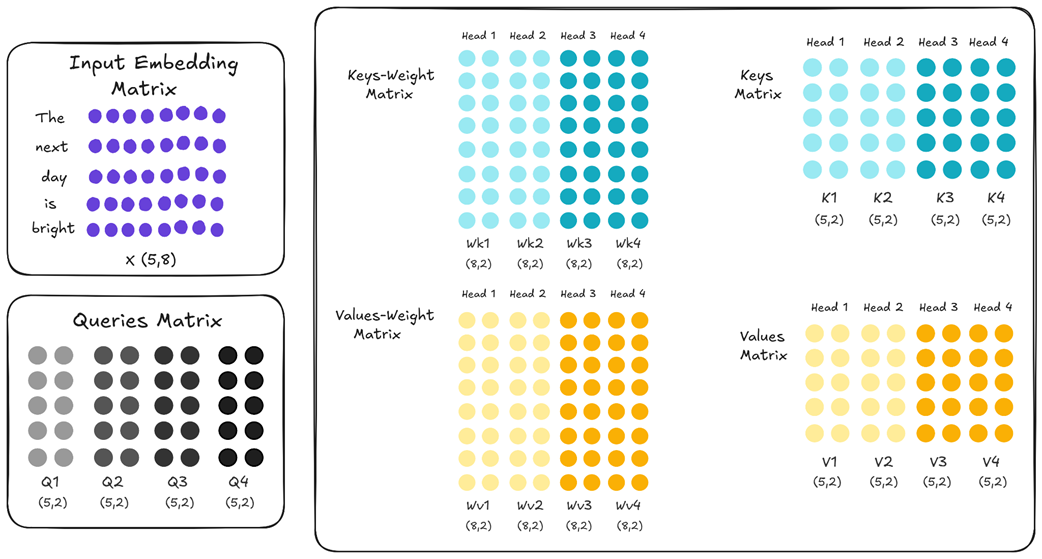
Four query heads form two groups, each with its own shared key and value projections. section 2.7.1
The number of groups g controls the trade-off. With g = n query heads, GQA becomes MHA; with g = 1, it becomes MQA. Intermediate values reduce the number of unique cached key/value pairs while retaining distinct projections across groups. section 2.7.2 section 2.8
For 16-bit KV storage, cache size in bytes is l × b × g × h × s × 2 × 2, where l is layers, b batch size, h head size, and s sequence length. The first factor of 2 accounts for keys and values; the second accounts for two bytes per stored value. Under the same dimensions, cache size scales with g rather than n. section 2.7.2
32 heads, 8 groups
Llama 3 8B uses 32 query heads and 8 KV groups, so every four query heads share one key/value head. Compared with 32 unique KV heads, the cache is four times smaller. section 2.7.2
To construct a GQA layer in PyTorch:
- Choose d_model, num_heads, and num_groups; require d_model to divide evenly by num_heads and num_heads by num_groups. section 2.7.3
- Set d_head = d_model / num_heads. Project queries to d_model dimensions and keys and values each to num_groups × d_head dimensions. section 2.7.3
- Ensure query heads in each group attend to their corresponding key/value group. Changing num_groups moves the layer between MQA-like and MHA-like behavior. section 2.7.3
The trade-off is empirical, not a guarantee of equal model quality. In one controlled comparison, GQA used 24 MB of KV cache and reached a best validation loss of 2.3776, versus MHA’s 48 MB and 2.3721. Multi-head latent attention takes a different approach, compressing cached information rather than only reducing unique KV projections. section 3.17 section 2.8


