Grouped-query attention (GQA) reduces the key-value (KV) cache needed during generation. Each query head has its own query, but heads in a group share key and value heads. The cache still grows with each processed token, but fewer KV heads mean fewer cached vectors per token. section 3.1.2 section 3.2.1
In multi-head attention (MHA), each query head has its own key-value pair. At the other extreme, multi-query attention (MQA) shares one pair across all query heads. GQA lies between them, capturing much of MQA’s memory savings while avoiding its quality compromises. section 3.1.2
Figure 3.5 Attention mechanisms and memory optimization strategies. Multi-Head Attention (MHA) maintains independent K,V pairs for each Q head — one pair per processed token, forming a growing cache. Grouped-Query Attention (GQA) groups Q heads to share K,V pairs (here 6 Q heads in 3 groups, each sharing one K,V pair per token). Multi-Query Attention (MQA) compresses to the extreme: all Q heads share a single K,V pair per token.
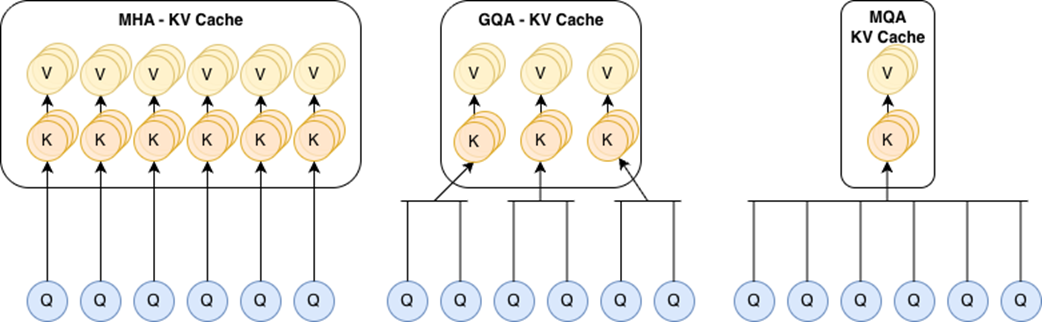
Compare the head arrangements: six query heads share three KV pairs in the GQA example. section 3.1.2
Cache budget at a 4:1 grouping ratio
Consider six layers and 12 query heads. MHA caches 8 tokens × 12 KV heads × 2 vectors × 6 layers = 1,152 vectors. With three KV heads, GQA caches 32 tokens × 3 KV heads × 2 vectors × 6 layers = 1,152 vectors. This is an illustrative vector count, not a measured byte-level benchmark. section 3.2.1 section 3.1.2
Projection dimensions reveal the grouping in Llama-3.2-1B: the query projection outputs 2,048 features, while the key and value projections each output 512. The output projection recombines attention-head outputs into an embedding. The model uses a 4:1 query-to-KV grouping ratio. section 3.2.1 section 3.3
(q_proj): Linear(in_features=2048, out_features=2048,
                             ➥ bias=False)  #A
(k_proj): Linear(in_features=2048, out_features=512, bias=False)
(v_proj): Linear(in_features=2048, out_features=512, bias=False)
(o_proj): Linear(in_features=2048, out_features=2048, bias=False)  #B
Inspect the separate query, key, value, and output projection dimensions. section 3.2.1
Shared KV projections also complicate attention-head pruning: unlike in classic MHA, heads in the same group are not independent across all three projections. section 3.2.1


