liveBook · Manning

Hadoop catalog

As explained in Architecting an Apache Iceberg Lakehouse

A catalog implementation that resolves Apache Iceberg tables from filesystem paths and stores their metadata without requiring a separate catalog service.

The Hadoop catalog resolves Apache Iceberg tables through filesystem paths and stores metadata in directories beneath a warehouse root. It requires no catalog service, but provides limited coordination for concurrent writers and no remote API. section 7.4.1

Its operational profile is defined by these tradeoffs:

  • Uses HDFS, Amazon S3, or Azure Data Lake Storage for filesystem-based metadata operations. section 7.4.1
  • Organizes table names into namespace directories under a shared warehouse. section 7.4.1
  • Fits local development, isolated environments, and tightly controlled single-user workloads, but is discouraged for production deployments involving multiple tools or writers. section 7.4.1

Lightweight Python lakehouse

A startup uses Hadoop catalog with PyIceberg to create and manage Iceberg tables directly in Amazon S3 from developer laptops, avoiding additional services while retaining a path to REST or enterprise catalogs later. section 7.5.8

Figure 7.10 With a Hadoop catalog, a file called VERSION -HINT.TEXT is used to discover the metadata file instead of a catalog service that you would send a request to.
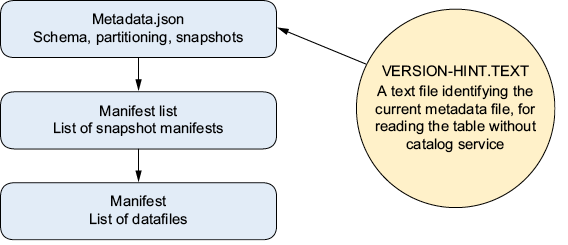
Shows how VERSION-HINT.TEXT helps discover a table's metadata file without querying a catalog service. section 7.4.1

How Architecting an Apache Iceberg Lakehouse covers it

How deep it goes
Explains directory layout, namespace handling, metadata discovery, strengths, and production limitations, but stops short of detailed transaction internals.
Examples
Uses warehouse namespace paths, VERSION-HINT.TEXT, and a Python-and-S3 startup deployment as concrete examples.
What it assumes
Assumes familiarity with Apache Iceberg tables and compatible filesystem storage while requiring no separate catalog-service infrastructure.
What you can do after
Operate/configure filesystem-backed Iceberg tables with PyIceberg while recognizing when centralized catalog coordination is needed.
How it connects
Connects Apache Iceberg, PyIceberg, filesystem storage, Hive catalog, REST catalogs, and enterprise catalog migration.

Related concepts

This explainer was generated by Manning's knowledge graph from the text of Architecting an Apache Iceberg Lakehouse. The section links point to the parts of the book it draws on.