Hadoop Distributed File System (HDFS) stores very large files across clusters of commodity machines. It divides files into fixed-size blocks, replicates those blocks across nodes, and exposes a distributed filesystem interface for processing frameworks. By colocating storage and compute, HDFS supports high-throughput batch processing with reduced network costs. section 1.4 section 5.4.2
HDFS is most useful when organizations value:
- Parallel access to large files and predictable throughput on commodity or self-managed hardware. section 5.2.1 section 5.5.1
- Data locality and tight integration with MapReduce, Apache Spark, and existing Hadoop clusters. section 5.4.2
- Incremental lakehouse modernization, such as managing Parquet files in HDFS with Apache Iceberg. section 5.4.2
The tradeoff is operational overhead: teams must provision disks, configure replication, balance clusters, and handle fault recovery. HDFS lacks the elastic scaling, global accessibility, and cloud-native integration of object storage, so it increasingly functions as a transitional layer for new lakehouse deployments. section 5.2.1 section 5.4.2
Figure 5.5 A single file is stored across multiple blocks in a block storage system.
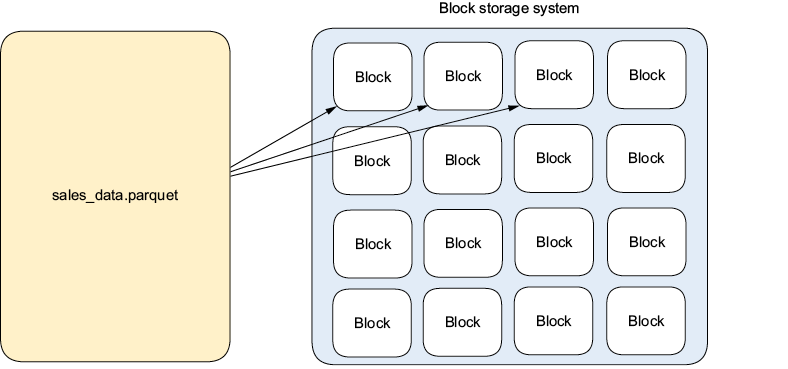
Shows how a single file is divided across blocks and distributed through a block storage system. section 5.2.1
