Hinge loss measures classification disagreement through the signed margin zᵢ = yᵢ(θ · xᵢ + θ₀). It penalizes examples with insufficient margin and is minimized by stochastic gradient descent. section 5.2
Its optimization behavior follows from its piecewise-linear shape:
- Use zero gradient when the signed margin exceeds 1. section 5.2
- Use a subgradient at margin 1 because the maximum operator is not differentiable there. section 5.2
- Update the classifier parameters for margins at or below 1 through stochastic gradient descent. section 5.2
Figure 5.7 Hinge loss, 0–1 loss, and log-loss functions
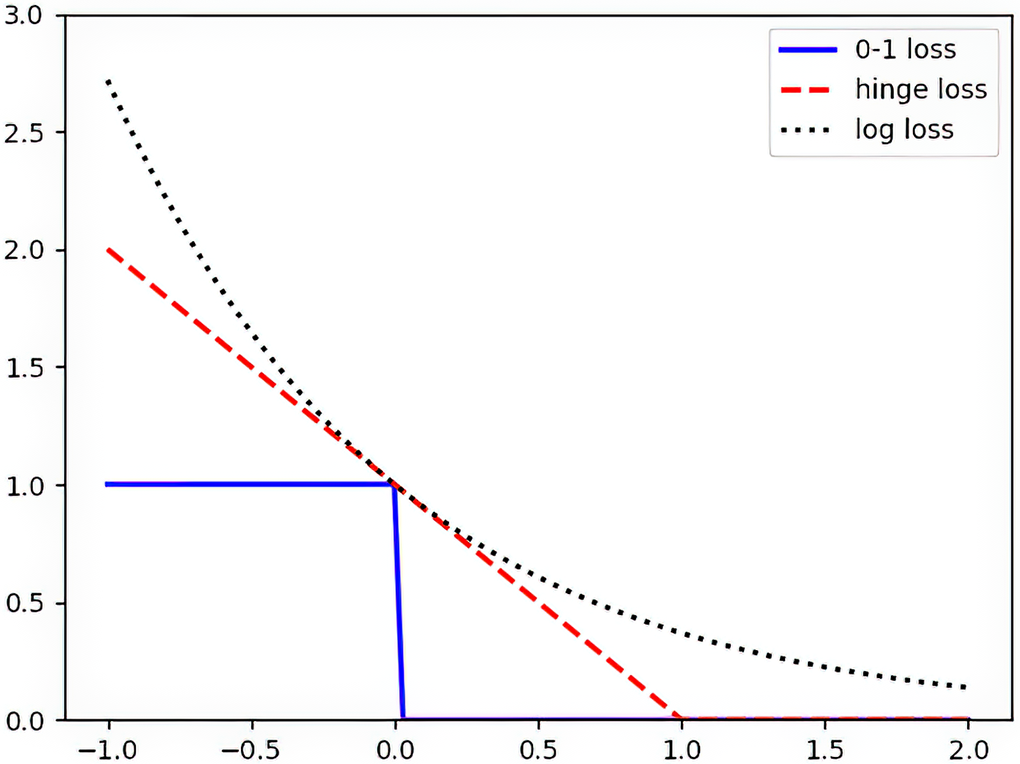
Compare hinge loss with 0–1 loss and log-loss across classification margins. section 5.2

