A RAG system can have the right document and still fail to retrieve it. A short question about a deployment pipeline, for example, may look unlike the architectural document that answers it. HyDE (Hypothetical Document Embeddings) addresses this query–document mismatch by searching with an imagined answer rather than the original question. It can help when the answer is missing from retrieved context or buried below less useful matches. section 7.0
At query time, HyDE changes what gets embedded:
- Prompt an instruction-following LLM to write a plausible document answering the question. section 7.2
- Embed that document with an encoder and search for similar documents in the corpus, rather than embedding the question for the search. section 7.2
- Use retrieved documents for factual grounding. The imagined document models relevance; it is not evidence for the final answer. section 7.0
Figure 7.2 HyDE Workflow: HyDE separates relevance modeling (LLM generation g(q)) from semantic encoding (f()) and retrieval over a corpus.
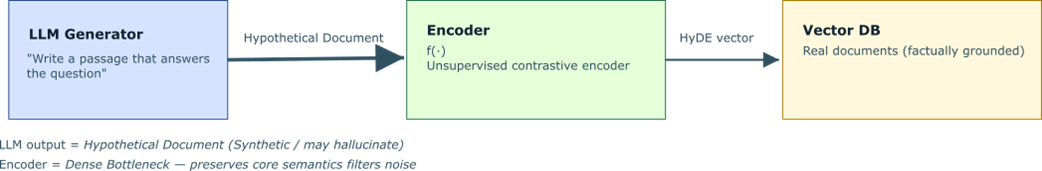
The workflow separates the LLM’s relevance modeling from encoding and corpus retrieval. section 7.2
Finding a clinical guideline
A direct search for “Optimal treatment for atrial fibrillation in elderly patients” may return general articles containing those words. A hypothetical answer can introduce concepts such as stroke risk, bleeding risk, anticoagulation, and DOACs. Searching with its embedding is more likely to reach relevant clinical guidelines and abstracts. The generated clinical claims remain a search aid, not medical advice. section 7.5
HyDE needs no labeled relevance pairs, making it useful to try in new domains or languages. It still depends on the generator knowing enough to write a useful proxy and on an appropriate encoder. An unseen internal codename may yield only a generic passage. More seriously, a confidently wrong interpretation can steer retrieval toward the wrong documents. Averaging multiple hypothetical documents or combining their vector with the original query vector can hedge against a poor generation; reranking or groundedness checks remain important downstream. section 7.4 section 7.7

