IQ4_XS is a llama.cpp quantization format that uses four-bit indices and a codebook. Its importance-aware bit allocation can deliver a smaller model with lower perplexity than Q4_K_M: one comparison measured 3.45 GB and PPL 5.36 for IQ4_XS, versus 3.89 GB and PPL 5.43 for Q4_K_M. section 10.3.4
Choose the format with runtime and workload constraints in view:
- Prefer IQ4_XS for decode when the runtime supports its 16-entry codebooks; measured x86 CPU kernels lead Q4_K_M by 6–13%. section 10.4.4
- Use Q4_K_M as a compatibility fallback for older GPU kernels, CPUs older than Skylake, or embedded targets without efficient byte-permute. section 10.4.5
- Treat benchmark rankings as hardware-specific: AMX narrows IQ4_XS’s lead, and older x86 CPUs can shrink or invert its advantage over Q4_K_M. section 10.4.4 section 10.3.4
Figure 10.5 Wikitext-2 perplexity (4 chunks × 512 tokens, CPU-only) versus on-disk size. F16 (12.85 GB, PPL 5.27) anchors the lossless baseline. F16 → Q8_0 → Q5_K_M is a clean staircase down. Q4_K_M sits to the upper side of Q5_K_M as expected. IQ4_XS sits to the lower-left of Q4_K_M—smaller and lower perplexity at the same bit tier.
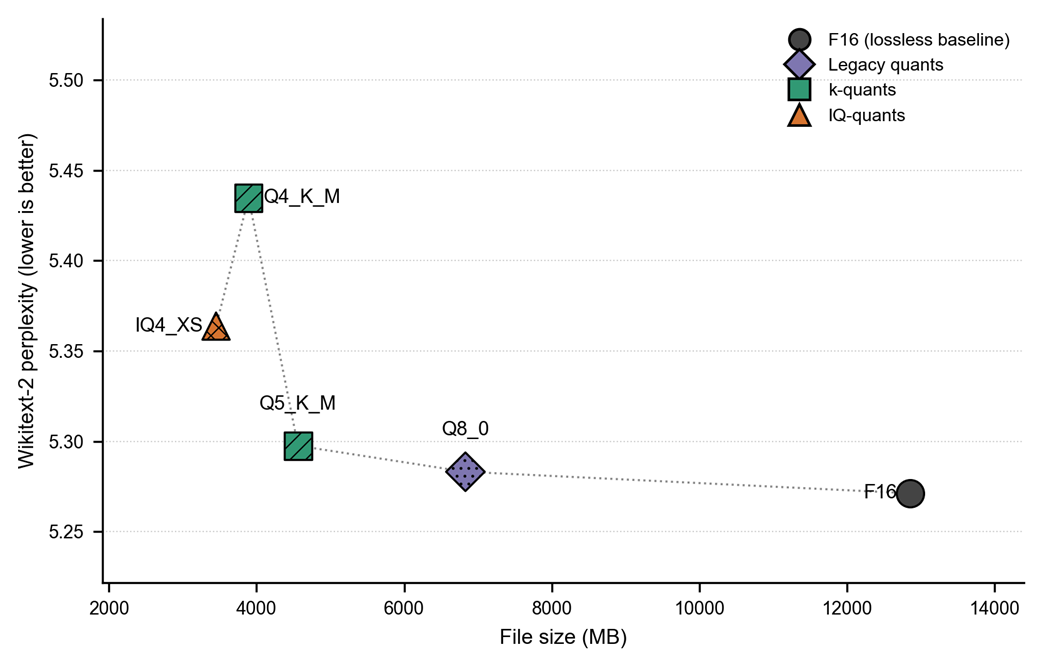
Compare model size and perplexity across quantization formats; IQ4_XS falls below and to the left of Q4_K_M in this CPU-only test. section 10.3.4
Figure 10.10 IQ4_XS decode throughput as a multiple of Q4_K_M decode throughput on the same hardware, same model. Ratios above 1.0 mean IQ4_XS wins despite being the more complex format; ratios below 1.0 mean codebook lookups serialize faster than the bandwidth saving recovers. Measured: avx2 1.13, avx512 1.13, avx512-amx 1.06. The avx2 column is the kernel family Section 10.3 worried about, and the lead does not invert there.
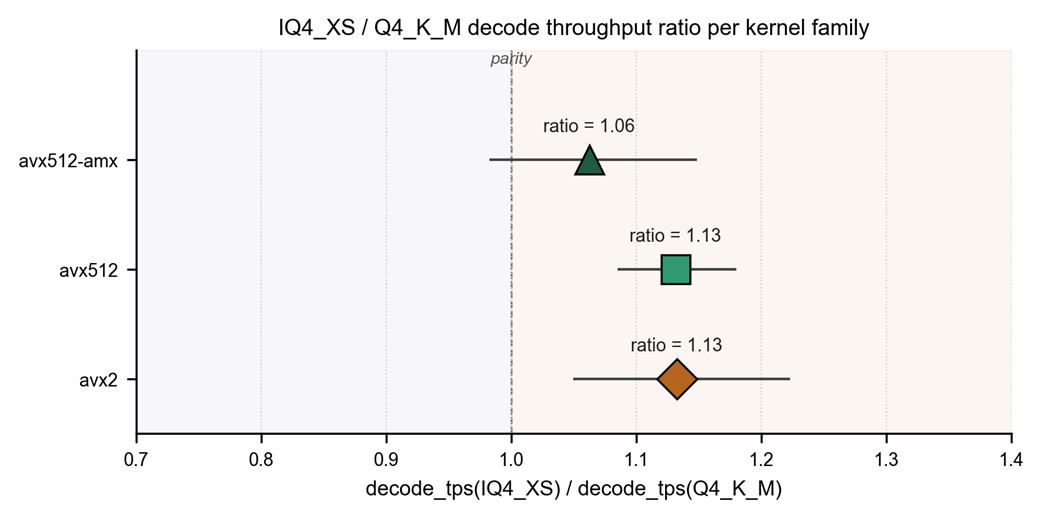
See how IQ4_XS decode throughput compares with Q4_K_M across AVX2, AVX-512, and AVX-512 with AMX. section 10.4.4
