IQ quantization compresses model weights into low-bit, non-uniform codebooks. Unlike formats that choose scales from each block alone, IQ quantization uses an importance matrix to weight codebook fitting toward tensors that matter most to loss. section 10.2.1 section 10.3.3
For the IQ4_XS workflow:
- Run a calibration corpus through the F16 model with llama-imatrix; it records per-tensor activation magnitudes in a sidecar GGUF. section 10.3.3
- Pass the importance matrix to llama-quantize for codebook fitting. In the described IQ4_XS recipe, quantizable tensors use IQ4_XS except output.weight, which uses Q6_K. section 10.3.3
IQ4_XS versus Q4_K_M
Both are nominally 4-bit formats, but IQ4_XS occupies 3.45 GB versus 3.89 GB for Q4_K_M in the reported conversion. The IQ4_XS recipe upgrades fewer tensors; its reported throughput is also optimal across the tested CPU kernels. section 10.3.3 section 10.6
Figure 10.2 GGUF quantization formats by bits per weight, including per-block scale and metadata overhead. Legacy quants (dotted) span Q4_0 (4.50 bpw) through Q8_0 (8.50). K-quants (diagonal) span Q2_K (2.62) through Q6_K (6.56). Bars show each base format's bpw; the recipe-level M-variants (Q3_K_M, Q4_K_M, Q5_K_M) sit 0.2–0.4 bpw above their base because of bumped tensors, as 10.2.4 makes explicit. IQ-quants (cross) span IQ1_S (1.56) through IQ4_XS (4.25). Importance-matrix calibration pushes below the k-quant floor. Reference dashes mark INT4 and INT8.
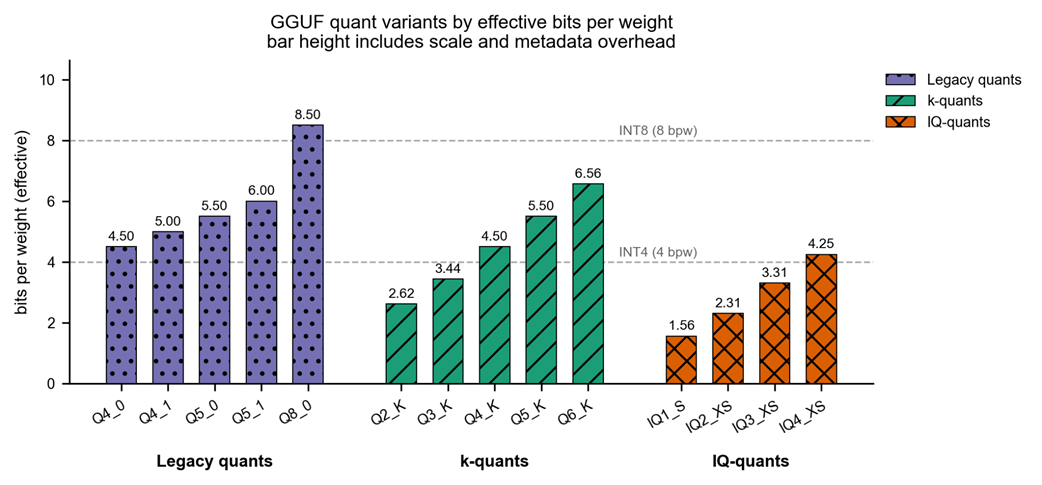
Compare GGUF formats by effective bits per weight; the chart shows IQ formats spanning IQ1_S through IQ4_XS. section 10.2.1
Listing 10.6 imatrix calibration (one-time, IQ-quants only)
./build/bin/llama-imatrix \
    -m _models/Llama-2-7b-hf-F16.gguf \
    -f _models/imatrix_calibration.txt \
    -o _models/imatrix.gguf \
    -c 512 --chunks 10 \
    --n-gpu-layers 0                       CPU-only one-shot calibration
# Wall-clock: 89.2s. Output: imatrix.gguf, 4.4 MB.
# Run logged: "computing over 3 chunks, n_ctx=512, batch_size=2048, n_seq=4"
Use the calibration command as a concrete starting point for generating an importance matrix with llama-imatrix. section 10.3.3
