A key up-projector is a learned linear transformation that reconstructs full attention key vectors from a compressed latent key-value representation. In Multi-Head Latent Attention, it enables the model to cache one small cKV matrix instead of separate full-dimensional keys and values. section 3.2.2
The key up-projector participates in the latent-cache attention path:
- Store historical key and value information in the compressed cKV cache. section 3.2.2
- Multiply cKV by the key up-projector Wuk to obtain the full key matrix K. section 3.2.2
- Decompress the cache on demand, then use the reconstructed keys in ordinary attention score and softmax calculations. section 3.4.3
Five-token decoding step
For an updated cKV cache with shape 5 × 4, multiplying by Wuk produces the full 5 × 4 key matrix. A fresh query for “bright” then attends over those reconstructed keys; the parallel value projection supplies the context vector. section 3.4.3
Figure 3.9 Decompressing the updated latent cache into the full Key and Value matrices using the up-projection matrices.
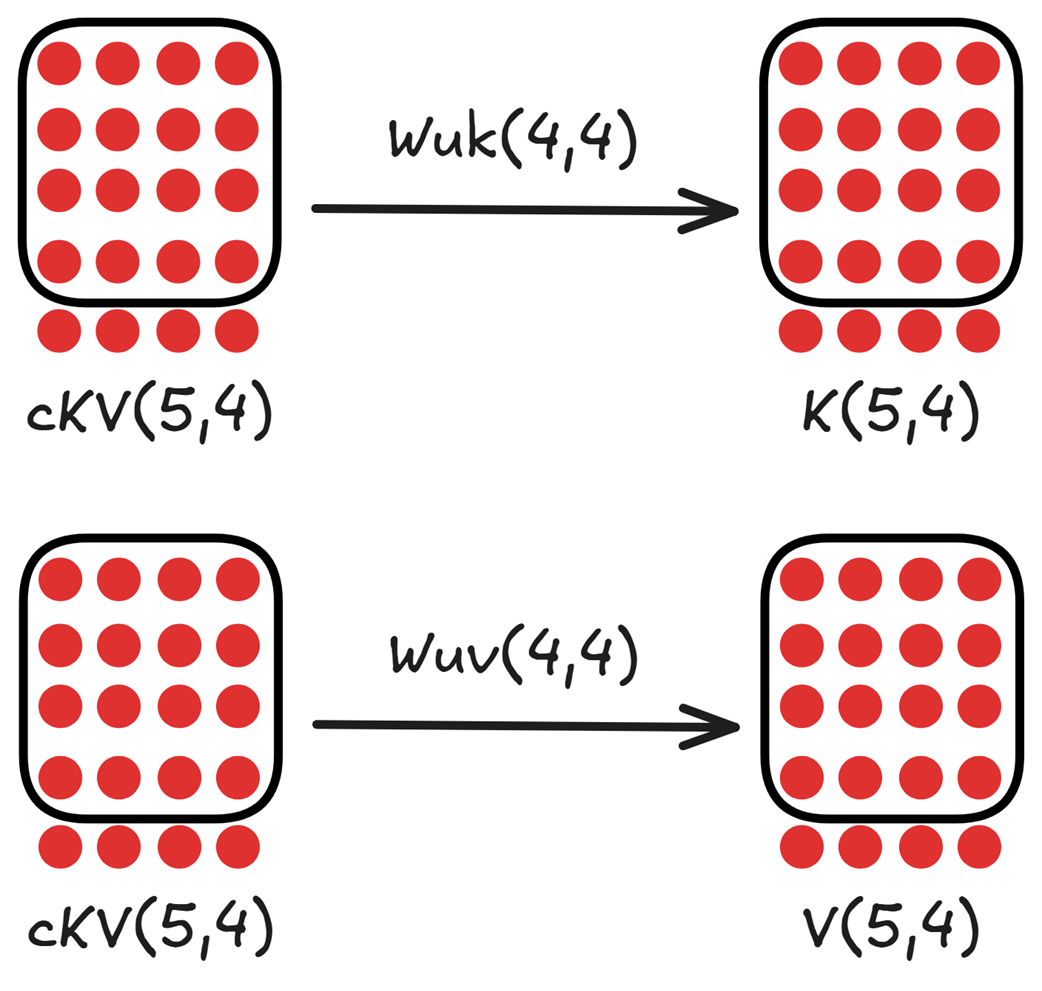
Visualizes decompression of the updated latent cache into full key and value matrices through the two up-projection matrices. section 3.4.3
