A value up-projector is a learned linear transformation that reconstructs full value vectors from a compressed latent key-value representation. Multiplying the cached cKV matrix by Wuv produces the value matrix V needed by attention. section 3.2.2
Use the projector during latent-cache attention in three steps:
- Store historical key and value information in the compact cKV cache rather than caching full matrices. section 3.2.2
- Multiply cKV by Wuv to reconstruct the full value matrix V on demand; multiply it by Wuk in parallel to reconstruct K. section 3.2.2 section 3.4.3
- Apply ordinary attention: score the fresh query against K, normalize with softmax, and combine the weights with V. section 3.4.3
Reconstructing a value matrix
With an updated cKV cache of shape 5×4 and Wuv, multiply cKV by Wuv to obtain a 5×4 value matrix. Attention then combines this V with weights computed from the fresh query and reconstructed K for “bright.” section 3.4.3
Figure 3.9 Decompressing the updated latent cache into the full Key and Value matrices using the up-projection matrices.
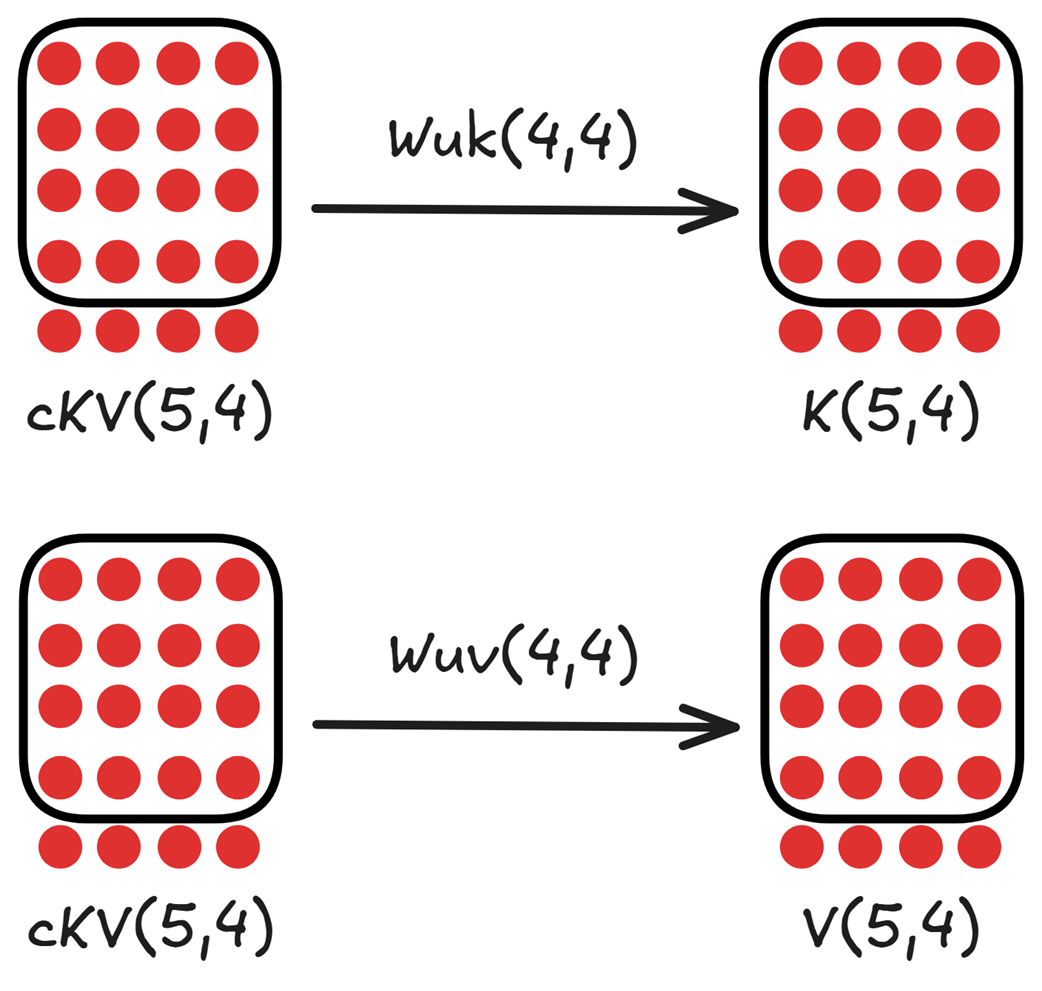
Trace how the updated latent cache is decompressed into full K and V matrices through the up-projection matrices. section 3.4.3
