LLM-as-judge evaluation uses a language model to assess generated responses for quality, factual consistency, and hallucination. In RAGAS, faithfulness is computed with this approach, producing more nuanced judgments than rule-based systems. section 6.5.2
The pattern supports RAG evaluation by:
- Assessing whether generated answers remain factually grounded in retrieved information. section 6.5.2
- Providing nuanced quality judgments beyond basic or rule-based metrics. section 6.5.2
- Supporting systematic comparison of retrieval and generation changes during production-aligned testing. section 6.5.2
RAGAS faithfulness
RAGAS uses an LLM-as-judge approach to compute faithfulness, while HHEM uses a classification model for the same hallucination and factual-consistency concerns. section 6.5.2
Figure 6.7 RAGAS Core Metric extensively covers LLM Grounding and Response (Source)
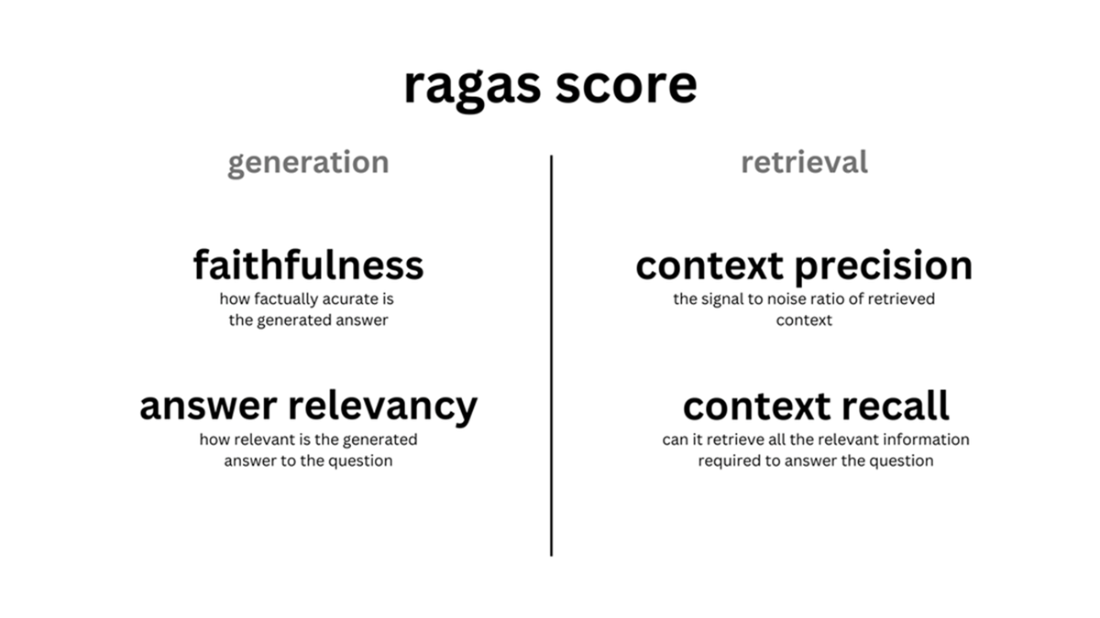
Use the figure to inspect how RAGAS metrics connect grounding with generated-response evaluation. section 6.5.2




















