A long-range dependency links elements far apart in a sequence. Character-level models must preserve relevant information across many steps, making it easier to drift off topic or lose coherence. section 4.1
Recurrent neural networks carry information forward step by step. Self-attention instead connects every token directly to every other token at each layer, so distance does not increase the computational path between them. Convolutional models need stacked layers to connect distant positions. section 5.1.1 section 4.1
A distant connection
In the Transformer example, “cheese” can attend directly to “mice,” however many words separate them. Character-level generation faces a longer sequence of steps over which it must preserve coherence. section 5.1.1 section 4.1
Figure 4.1 This image, from Chris Olah’s work (discussed in the next section), shows a chain-like structure representing an RNN. It illustrates how RNNs process data sequentially, with the output of one step feeding into the next. The recurrent, linked modules reflect the RNN’s ability to carry information forward, making it well suited to learning patterns that unfold over time, such as time series, text, or audio. Used with permission granted by the author (Chris Olah).
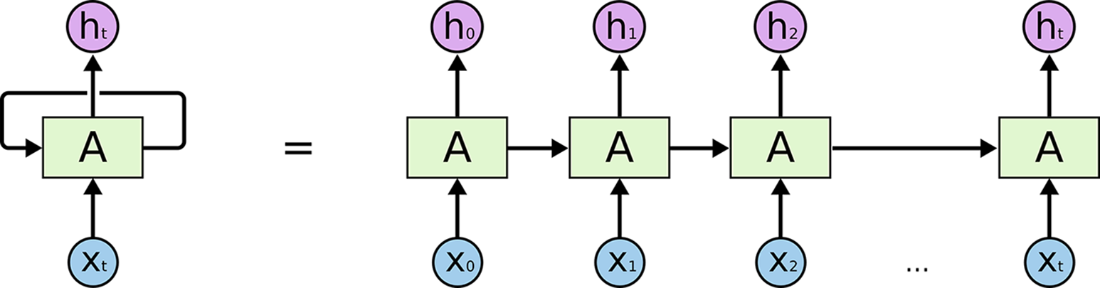
The RNN chain diagram illustrates sequential information flow, a contrast to direct self-attention connections. section 4.1 section 5.1.1


