Masked attention restricts attention connections so a decoder position cannot use disallowed information, especially future output tokens. It preserves causality during one-token-at-a-time generation. section 11.3
The masking mechanism operates as follows:
- Construct a mask matrix M containing zeros for permitted connections and negative infinity for prohibited connections. section 11.3
- Add M to the attention scores before applying softmax. section 11.3
- Let softmax preserve permitted connections while converting masked negative-infinity scores to zero, removing those connections from the output. section 11.3
Autoregressive translation
While generating a translated sentence, the decoder masks tokens that have not yet been generated, preventing later output words from influencing earlier predictions. section 11.3
Figure 11.10 Transformer architecture
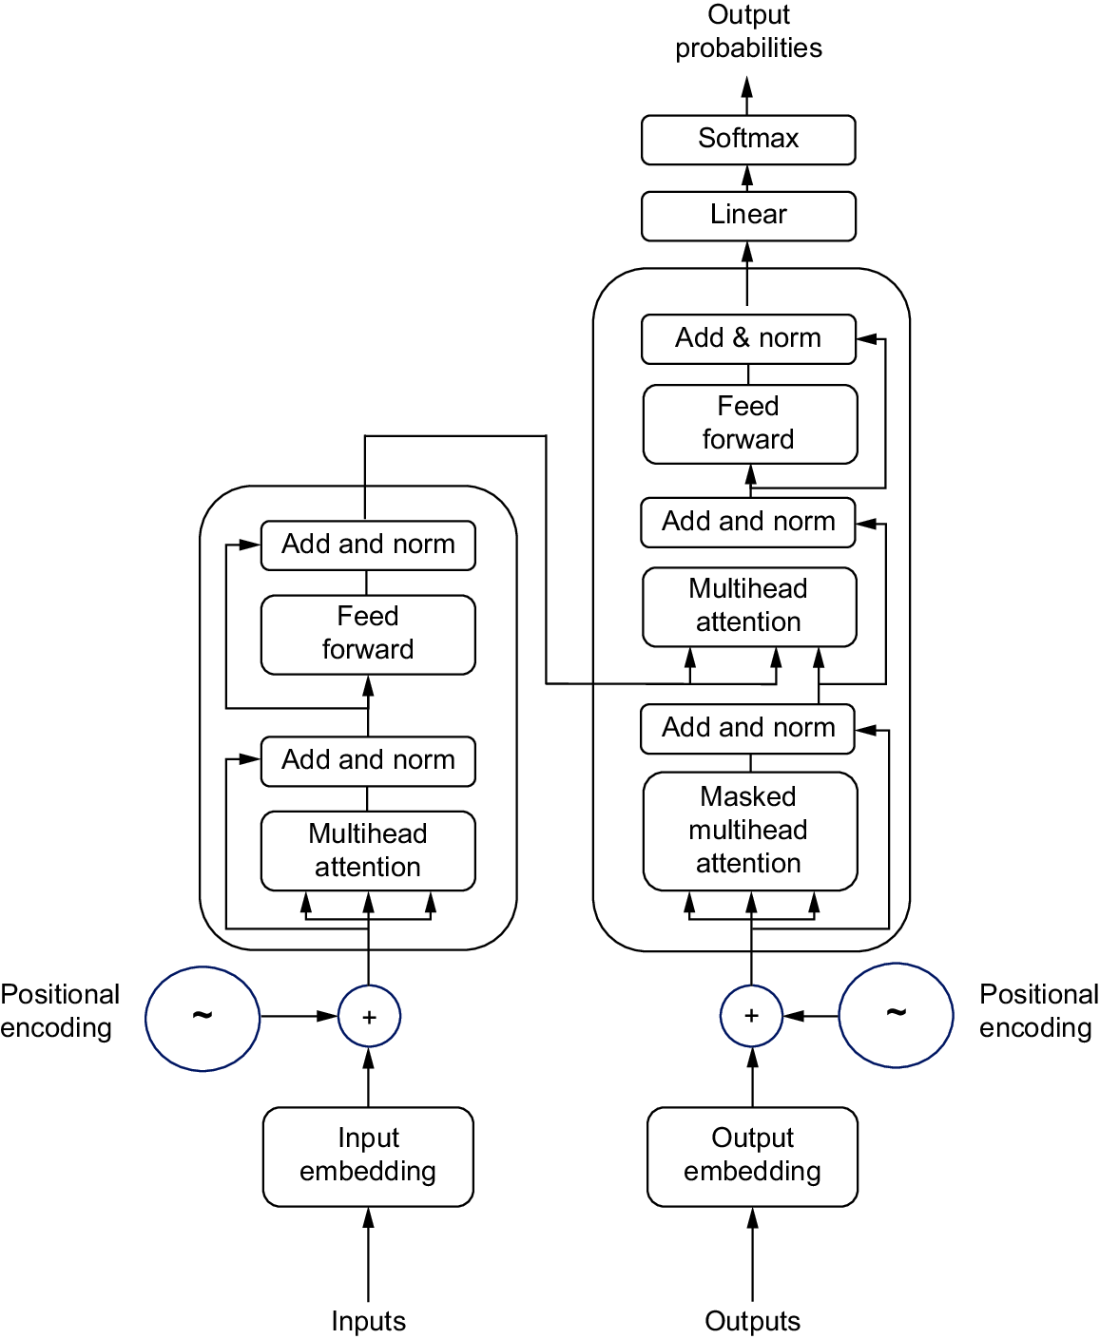
Use the transformer architecture figure to locate masked multihead self-attention inside the decoder. section 11.3





