MLCEngine is MLC LLM’s unified high-performance inference engine for running compiled language models across platforms. It exposes OpenAI-compatible chat completions through Python, JavaScript, iOS, Android, and a REST server, using one engine and compiler across deployment targets. section 11.3
A typical deployment path prepares the model before constructing the engine:
- Convert Hugging Face model weights to MLC format with a selected quantization type and target device. section 11.3
- Generate the chat configuration with the model’s conversation template. section 11.3
- Compile the configuration into a platform-specific model library. section 11.3
- Instantiate MLCEngine with the converted model directory and compiled model library, then call chat completions locally or through REST. section 11.3 section 11.5
Python chat completion
from mlc_llm import MLCEngine\nengine = MLCEngine(model="./dist/model", model_lib="./dist/libs/model-cuda.so")\nresponse = engine.chat.completions.create(messages=[{"role": "user", "content": "What is the meaning of life?"}], model="./dist/model", stream=False) section 11.3
Figure 11.3 The end-to-end workflow for MLC LLM, from model conversion to deployment on the supported platforms’ native runtimes
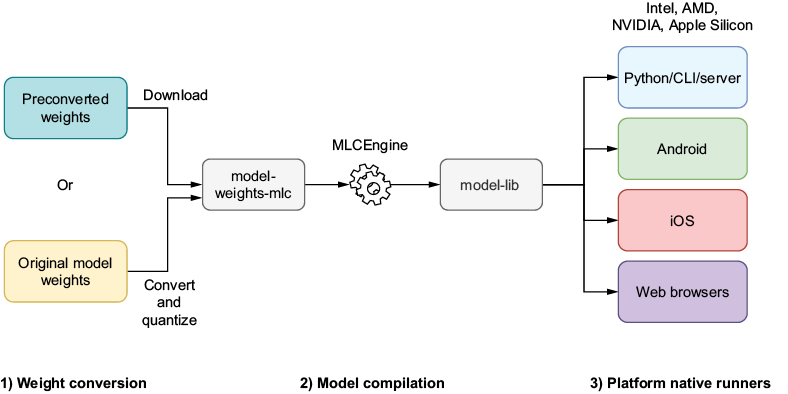
Follow the end-to-end path from model conversion through compilation and deployment on supported native runtimes. section 11.3
