Multimodal data combines different kinds of input, such as text and images. A language-model prompt can pair a question with an image so the model can answer about what it sees. section 6.2.1 section 1.3.1
Ask a question about an image
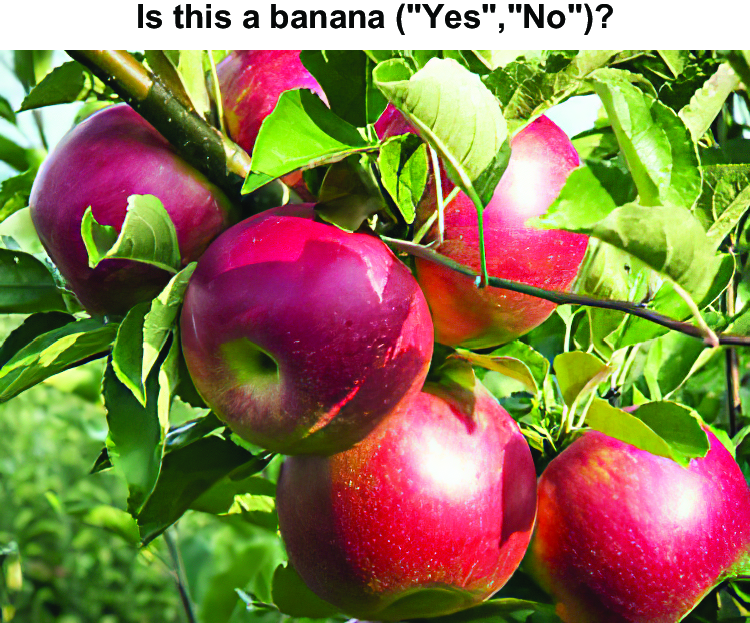
A prompt pairs an image with the question “Does this picture show a banana?” The expected answer is “No.” section 6.2.1
Figure 6.1 Multimodal prompt containing an image and text. The prompt instructs the language model to decide whether the picture shows a banana. In this case, the expected output is “No” (otherwise “Yes”).
See the image-and-text prompt example for a visual question-answering task. section 6.2.1


