Negative sampling trains link-prediction models with a manageable subset of nonexistent edges instead of evaluating every possible negative relationship. It addresses the class imbalance between existing and nonexistent edges. section 5.2.3
A graph autoencoder training step follows this pipeline:
- Encode the graph into a latent representation. section 5.2.3
- Draw new nonexistent edges each epoch with negative_sampling, matching the number of training edge labels. section 5.2.3
- Concatenate positive and negative edge indices, decode them, and assign labels 1 and 0 respectively. section 5.2.3
- Compute binary cross-entropy, backpropagate, and update the model; evaluate validation and test edges without resampling. section 5.2.3
PyTorch Geometric training step
Call negative_sampling on train_data.edge_index, use the returned neg_edge_index with the positive edge_label_index, and create matching zero labels before calculating BCEWithLogitsLoss. section 5.2.3
Figure 5.6 Overall steps for training our model for link prediction
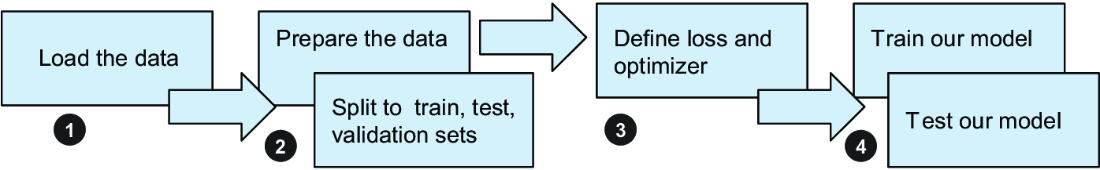
Follow the end-to-end link-prediction pipeline from graph encoding through sampled training edges and evaluation. section 5.2.3

