ParentDocumentRetriever improves retrieval context by embedding small child chunks while returning their larger parent chunks. Child chunks match detailed queries precisely; parent chunks preserve surrounding meaning for answer generation. section 8.4.1
Build the retriever from separate search and context layers:
- Split documents into coarse parent chunks for synthesis, then split each parent into smaller child chunks for granular matching. section 8.4.1
- Store child chunks and embeddings in a vector store such as Chroma, while storing parent documents in an InMemoryStore. section 8.4.1
- Configure ParentDocumentRetriever with both splitters and both stores, then ingest the source documents through add_documents(). section 8.4.1
- Choose child size for search granularity and parent size for context; benchmark against standard vector search before deployment because storage and computational costs increase. section 8.8
Retrieving context for a detailed query
After ingesting travel-guide pages, invoke the retriever with "Cornwall Ranger". Although the precise match resides in a small child chunk, the result is the larger South Cornwall document context rather than only the matching passage. section 8.4.1
Figure 8.4 Child chunk embeddings. A coarse document chunk is indexed with its own embedding and the embeddings generated from its smaller child chunks, allowing it to match effectively with both broad and detailed queries.
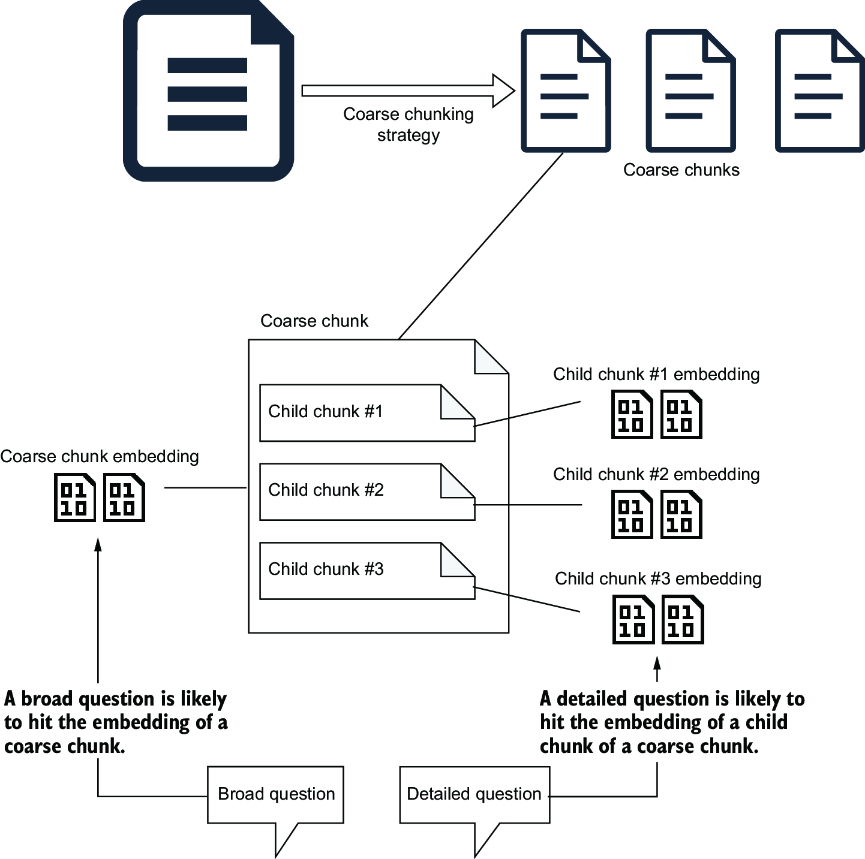
Use the child-embedding diagram to see how one coarse parent chunk supports both broad and detailed query matching. section 8.4.1

