An any-variate attention mechanism enables attention over flattened sequences containing any number of input series and exogenous features. Flattening removes the fixed-dimensionality constraint: adding or removing a feature changes sequence length rather than model dimensionality. section 6.1.1
The mechanism distinguishes series during attention:
- Flatten multivariate inputs into one long sequence for the encoder. section 6.1.1
- Associate each token with a variate index. section 6.1.1
- Add a learned binary attention bias that uses one parameter for tokens from the same series and another for different series. section 6.1.1
Figure 6.3 To handle an arbitrary number of variates, Moirai flattens the data into a single series.
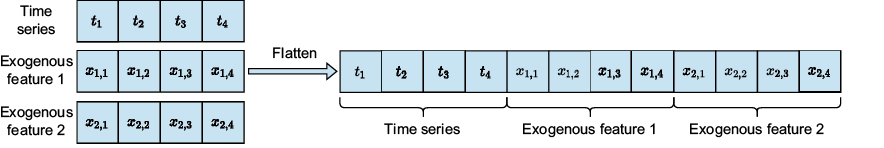
Illustrates how multiple variates become one flattened sequence before attention. section 6.1.1
