Persistence Query provides access to a configured ReadJournal so journal events can feed queryable views. It reads event-sourced state changes as Akka Streams, separating the write-side journal from stores optimized for reading. section 10.0 section 10.2
Select a plugin implementing the Persistence Query API, then obtain its ReadJournal through PersistenceQuery. Akka-maintained choices include Cassandra, Couchbase, and JDBC; a JDBC journal can use PostgreSQL for journal events and snapshots. section 10.2
ReadJournal queries expose infinite streams; after connecting, events may arrive at any time.
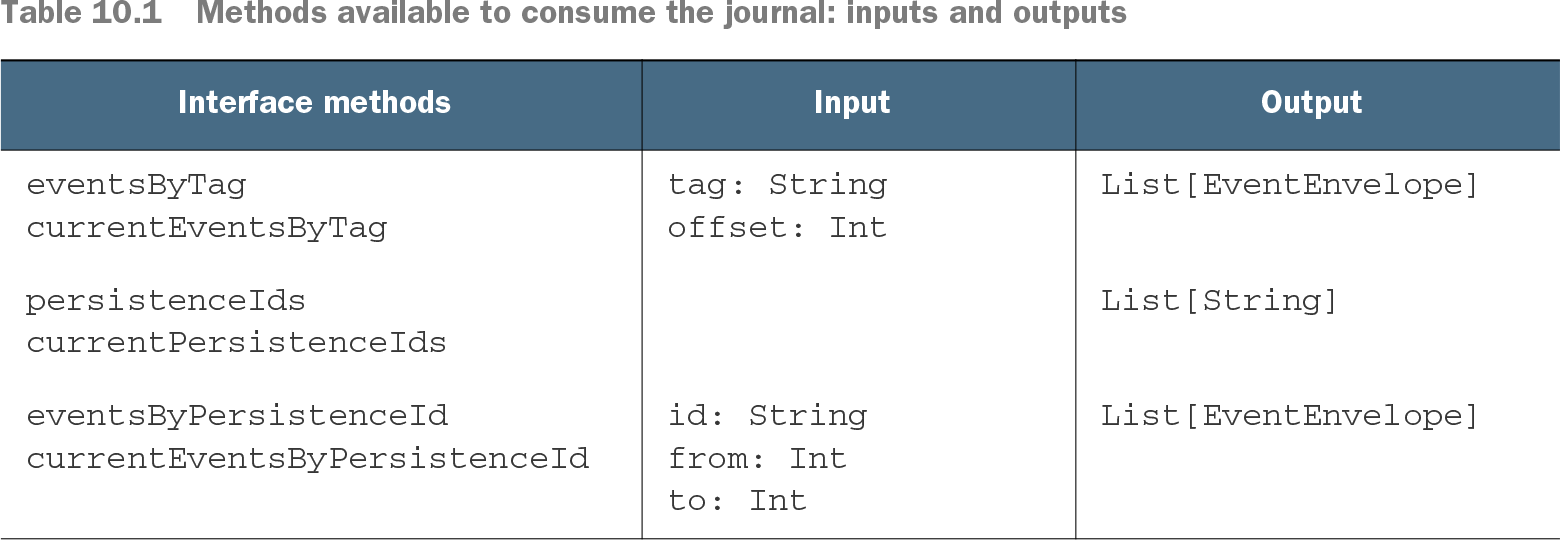
- Use persistenceIds or currentPersistenceIds to obtain persistence IDs. section 10.2
- Use eventsByPersistenceId or currentEventsByPersistenceId to read EventEnvelopes for one persistence ID over a sequence range. section 10.2
- Use eventsByTag or currentEventsByTag with a tag and offset. Pass Offset.noOffset to start at the beginning; retain offsets to mark the latest sequence number read. section 10.2
- Choose standard queries to read journal events from the beginning, or current queries to read only events appearing after execution. section 10.2
Print persistence IDs
Create a JdbcReadJournal with PersistenceQuery(system).readJournalFor using JdbcReadJournal.Identifier. Its persistenceIds Source can runForeach(println), producing IDs such as spcontainer-type-key|9 and spcontainer-type-key|11. section 10.2
A query stream can aggregate AddCargo events into totalWeight per container and write that view to another database or topic. This decouples reading from writing, supports scalable processing, and can filter hazardous cargo before enriching it through an external service. section 10.2.1
Table 10.1 Methods available to consume the journal: inputs and outputs (view table figure)
Compare ReadJournal methods by their inputs and emitted values when choosing ID-, tag-, or persistence-ID-based consumption. section 10.2