Pipeline focus organizes metadata and artifacts around a pipeline or training run rather than around model files. A shared training_run_id links the run to its output model, input data, metrics, and artifact URL, allowing navigation from execution to results. section 8.3.2
A pipeline-focused storage layer supports practical retrieval patterns:
- Preserve test, preproduction, and production entities under their associated training run. section 8.3.2
- Store the output artifact URL on the Training_Runs object and retrieve it through model or execution queries. section 8.3.2
- Add web-interface search for both pipeline and model views; pipeline focus and model focus are complementary rather than mutually exclusive. section 8.3.2
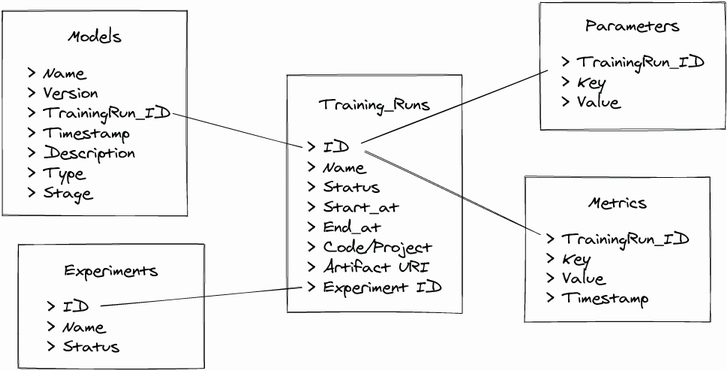
Use the entity-relationship schema to trace training_run_id links among executions, models, data, metrics, and artifact locations. section 8.3.2
