Positional interpolation (PI) rescales or interpolates RoPE frequencies so a model trained on shorter contexts can process much longer sequences without retraining. section 9.5.2
By stretching position information while remaining grounded in the training range, PI helps preserve coherence and limit the perplexity increase that commonly appears beyond the original context length. section 9.5.2
Extending context windows
PI and related refinements support model families such as Gemma 3 in scaling from earlier 2,000- or 4,000-token limits to 128,000 tokens or more. section 9.5.2
Figure 9.10 Illustration of the haystack problem. Unmitigated attention (grey) spreads probability mass almost uniformly across the sequence, making it difficult to isolate important tokens. Sharpened attention (black) produces a clear peak at the target position (dashed line), enabling retrieval even within a very long context.
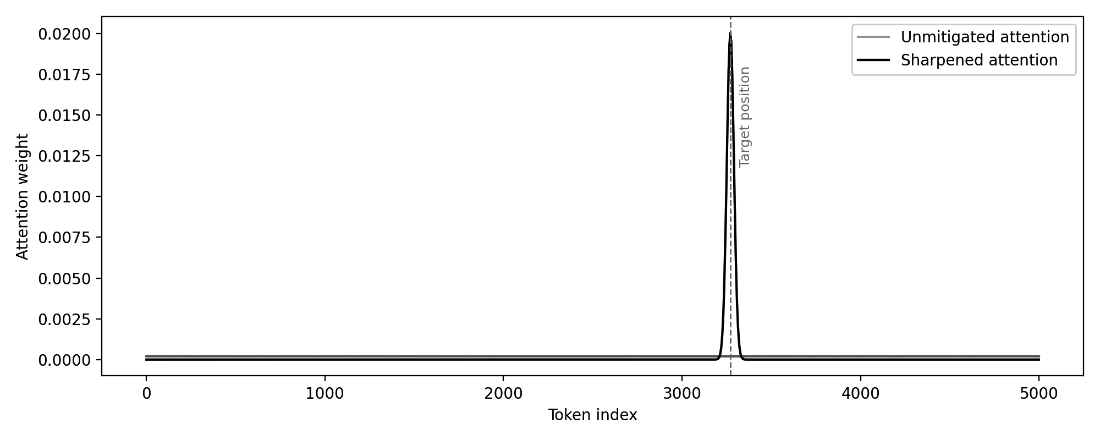
The haystack illustration shows why long-context extensions must preserve focused attention rather than merely accept more tokens. section 9.5.2
