A posterior distribution assigns probabilities to unknown model parameters after observing data. Let θ denote the parameters and x the observations. Bayes’ rule gives p(θ|x) = p(x|θ)p(θ)/p(x): the prior p(θ) represents initial beliefs, while the likelihood p(x|θ) measures how the model accounts for the data. As new observations arrive, a posterior can become the prior for the next update. section 1.4
The denominator p(x) = ∫p(x|θ)p(θ)dθ normalizes the distribution. This integral can be intractable in high-dimensional parameter spaces. The choice of prior matters: both its parameter values and its functional form affect the result. A conjugate prior has the same form as the posterior and permits a closed-form update. section 1.4
When a posterior is difficult to compute directly, two approaches are:
- Markov chain Monte Carlo (MCMC): sample from parameter space using a chain whose stationary distribution is the target posterior, then use the samples to estimate quantities of interest. Gibbs sampling and Metropolis–Hastings are two methods. section 1.4.1 section 2.9
- Variational inference (VI): choose a tractable distribution q and optimize it to approximate the posterior. section 1.4.1
Dirichlet–multinomial update
Compute the posterior using a Dirichlet prior and a multinomial likelihood, then examine how its shape changes with the posterior counts. This exercises a conjugate-prior update rather than a sampling approximation. section 8.4 section 1.4
Figure 1.4 A Bayes engine showing the transformation of a prior to a posterior as more data is observed
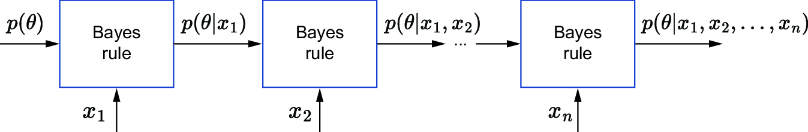
The Bayes engine depicts repeated updates: each new observation transforms a prior into a posterior that can inform the next update. section 1.4







