QLoRA adapts a foundation model without updating its large base weights: it freezes a 4-bit quantized base and trains small, full-precision LoRA adapters. This makes domain-specific fine-tuning possible with substantially less GPU memory than full-precision training. section 8.4
The quantization choice shapes the memory–error tradeoff:
- NF4 places its 16 levels according to standard-normal quantiles, concentrating resolution near zero where most weights fall. section 8.4
- A Llama-2-7B setup uses NF4, double quantization, bfloat16 compute, and rank-16 adapters attached to attention and feed-forward projections. section 8.4
Memory footprint
On an H100, the Llama-2-7B NF4 base occupies 3.60 GB; attaching adapters brings this to 4.24 GB, and peak training memory reaches 12.31 GB. The measured peak fits within a 16 GB T4. section 8.4
Figure 8.14 Weight reconstruction MSE across formats on OPT-6.7B fc1 layers (log scale). NF4 block-64 (shortest solid bars) achieves the lowest 4-bit MSE at 2.64×10⁻⁶ average. INT4 group-64 (diagonal hatch, same block size) is 1.44× worse. INT4 group-128 (GPTQ/AWQ default) is 1.73× worse. FP4 block-16 (backslash hatch) matches NF4 at 2.65×10⁻⁶ but uses 4× finer blocks. FP8 E4M3 per-tensor (vertical hatch, shortest bars) remains 12× better than any 4-bit format.
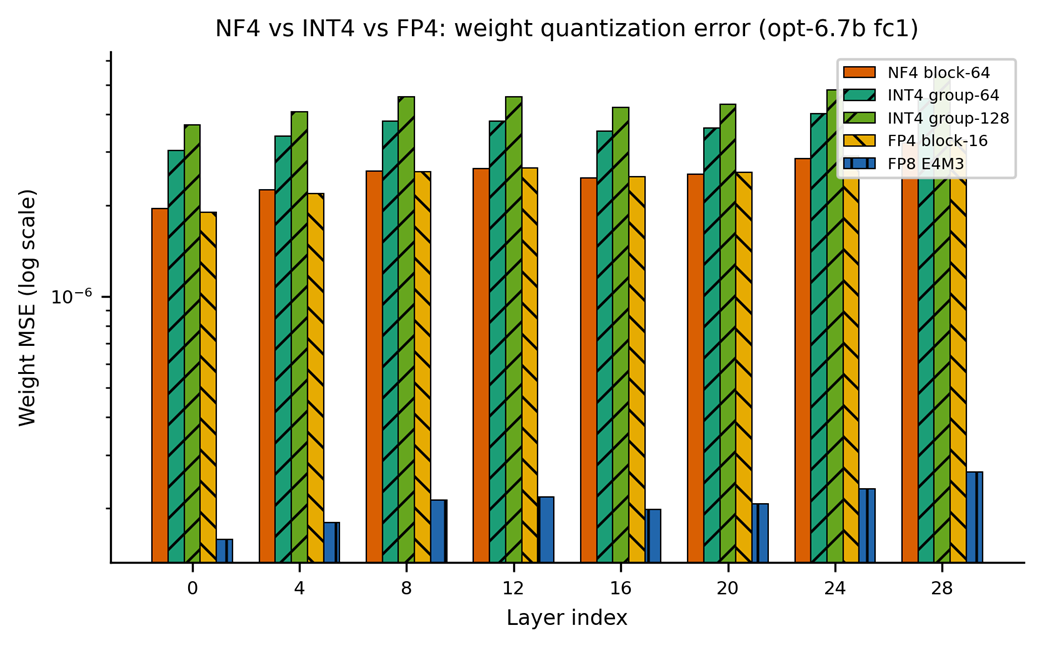
Compare reconstruction error across quantization formats: NF4 block-64 has the lowest measured 4-bit MSE in this OPT-6.7B comparison. section 8.4






