Query planning determines an efficient execution strategy, including which files or partitions a query must read. In Iceberg, metadata, snapshots, partition transforms, and file statistics guide pruning while preserving time travel and partition evolution. section 1.6 section 5.3.1
Planning improves performance and operational control through several mechanisms:
- Applies hidden partition transforms to filters on ordinary columns, pruning relevant partitions without exposing partition keys in the schema. section 2.6.4
- Uses Parquet footer and row-group statistics to skip unnecessary data and read only the required columns. section 5.3.1
- Enforces locality and access policies during planning, while logging queries, masking data, and tracking snapshots for auditability. section 9.5.6
Filtering timestamped events
A query filtering event_timestamp can use hour- or day-based hidden partitions even when it does not mention a partition column. Iceberg identifies relevant partitions and prunes files without changing the logical schema. section 2.6.4
Healthcare data locality
A region-aware catalog and Dremio enforce locality policies during planning for Iceberg tables partitioned by geography and department, while Power BI and JupyterHub consume controlled datasets. section 9.5.6
Figure 5.8 Using metadata in Parquet row-group footers, we can tell which row groups to scan and which to skip for faster reads.
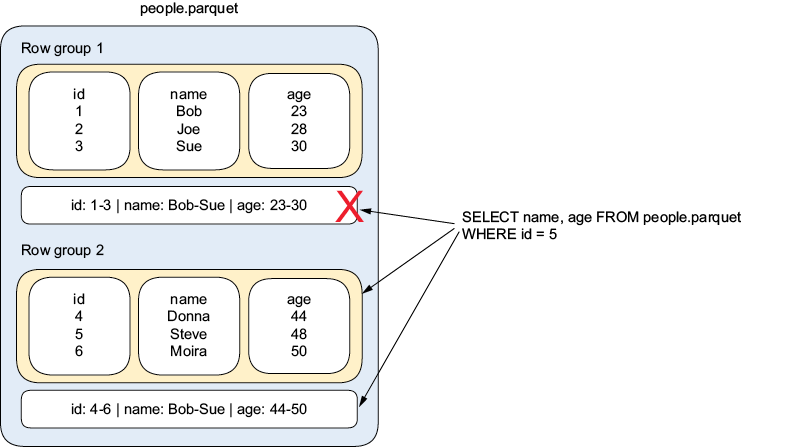
Shows how Parquet row-group footer metadata identifies data to scan and data to skip. section 5.3.1
