An attention score measures the relevance of a key to a query before normalization. For token queries Q and keys K, the raw score matrix is S = QKᵀ: row i, column j is the dot product of token i’s query with token j’s key. Queries represent what tokens look for; keys represent what tokens advertise. section 2.2.1
Figure 2.5 The dot product of the query and transposed key matrices produces the attention scores matrix. Each element in this matrix represents the relevance of one token to another.
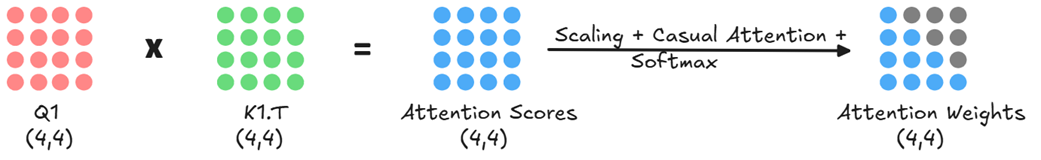
The matrix multiplication maps every query–key pair to one score. section 2.2.1
Four-token sequence
For “The next day is,” input embeddings of shape 4×8 are projected into Q and K matrices of shape 4×4. Multiplying Q by Kᵀ yields a 4×4 score matrix. Its fourth-row, second-column entry measures the relevance of “next” to the query for “is.” section 2.2.1 section 2.3.2
Scores are not yet attention weights. They are scaled to stabilize training, then a causal mask sets future-token positions to negative infinity. Softmax converts each row into weights that sum to 1; masked positions receive effectively zero weight. Setting masked scores to zero instead would leave them with positive softmax probability. Multiplying the weights by the value matrix produces context vectors. section 2.2.1
During autoregressive inference, the newest token needs only its own score row: multiply its query vector by the transpose of the full key matrix. Its resulting weights combine with the full value matrix to produce the newest context vector. New query, key, and value vectors are projected for the incoming token, while prior keys and values can be reused. section 2.4.1
A decoupled attention design can also construct scores from separate content and positional paths. If Q and K concatenate their respective content and positional components, then S = QcKcᵀ + QrKrᵀ. The first term is position-agnostic; the second incorporates RoPE. Their sum becomes the input to attention-weight calculation. section 3.14.2





