Redundancy keeps a generative AI application available by providing duplicate or alternate resources when a component fails or becomes unavailable. In production, it supports reliable service across retrievers, models, regions, and deployment environments. section 8.4.1 section 11.1
Apply redundancy alongside the mechanisms that make alternate resources usable:
- Deploy model services across multiple regions so the application can continue operating if one region becomes unavailable. section 10.5.1
- Combine redundancy with load balancing, API gateways, queuing, and stream processing to distribute traffic and manage demand spikes. section 10.5.1
- Plan failover and disaster recovery, then validate model performance, system health, and recovery behavior through regular testing and monitoring. section 11.1 section 11.7
- Balance availability against infrastructure requirements, operational complexity, and deployment cost when selecting virtual machines, containers, or serverless functions. section 11.2 section 11.7
Multi-model and multi-region service
A generative AI application can route requests among multiple model endpoints and deploy those services across regions. If one endpoint or region fails, routing and gateway controls can direct traffic to an available alternative. section 10.5.1 section 11.2
Figure 10.5 Classifier using multiple models
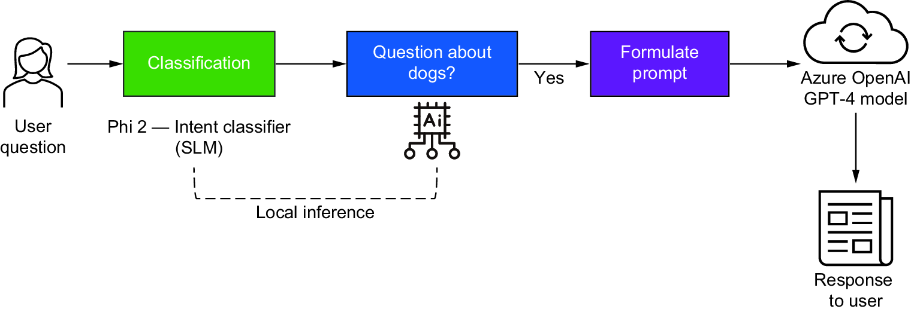
Visualizes a classifier architecture that uses multiple models and routes questions according to intent, illustrating alternate model resources within an application. section 10.5.1





