Imagine deciding whether to wear a jacket: the first question—“Is it raining?”—starts the decision process. In a decision tree, that topmost starting point is the root node. It contains the first yes-or-no question and represents the entire input dataset before any split. section 9.0
The root node establishes how a decision tree begins:
- Assign it level 0 and associate it with every training sample and its labels. section 9.2
- Evaluate features at the node and select a split using a metric such as accuracy, Gini index, or entropy. section 9.2
- Turn it into a decision node when splitting is allowed; otherwise, keep it as a leaf and assign the most common label. section 9.2
- A decision stump contains only the root node and two leaves, representing one immediate yes-or-no decision. section 9.0
Seeing the root in a geometric classifier
For a dataset with features x0 and x1, the root node corresponds to the first vertical boundary at x0 = 5. Its two sides become branches, and later horizontal boundaries split those branches further. section 9.4
Figure 9.2 A regular decision tree with a root node, decision nodes, branches, and leaves. Note that each decision node contains a yes-or-no question. From each possible answer, one branch emanates, which can lead to another decision node or a leaf. This tree has a depth of 2, because the longest path from a leaf to the root goes through two branches.
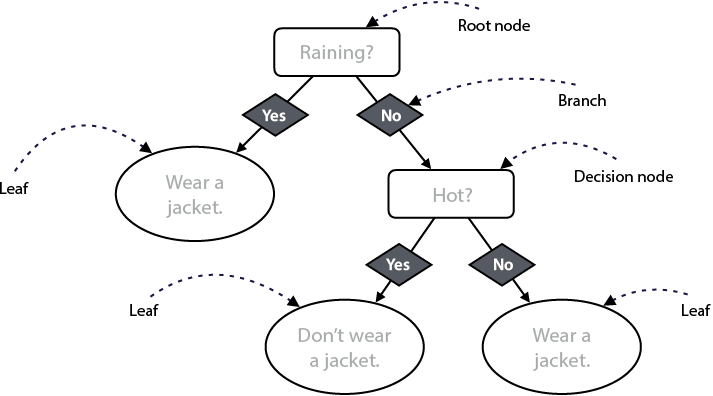
Use the tree diagram to trace the root's first question, its branches, later decision nodes, leaves, and overall depth. section 9.0




