Scaled-dot product attention turns relationships between input embeddings into weighted context vectors. It projects embeddings into query, key, and value matrices, divides query-key products by √dₖ, normalizes them with softmax, and uses the scores to combine values. section 9.1.2
The scaling step matters because:
- High-dimensional query-key products can produce small softmax gradients; multiplying by 1/√dₖ improves numerical stability. section 9.1.2
- The softmax produces positive scores that sum to one, creating weights for the value vectors. section 9.1.2
- The resulting Q × K matrix represents connections between words and supports efficient matrix-multiplication implementations. section 9.1.2
Equation 9.1 Self-attention outputs
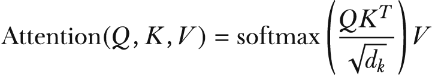
Use the self-attention equation to trace the scaling, normalization, and weighted-value steps together. section 9.1.2



