A failure taxonomy organizes recurring observations from system traces into broader categories. It turns scattered error notes into a shared language for evaluation, prioritization, and reliability work. section 10.2 section 10.5
Build a taxonomy from observed failures rather than predefined assumptions:
- Collect complete execution traces, including user requests, intermediate steps, tool calls, outputs, and errors. section 10.2
- Review traces through open coding: describe what went wrong in concise, free-form notes and focus on the first error. section 10.2.3 section 10.2
- Group similar observations into broader categories, then check new traces until no new failure types emerge. section 10.2.3
- Analyze category frequency and severity, and repeat the process after major system changes. section 10.2 section 10.2.3
From observations to categories
Notes such as “Citations do not match the source,” “Sources unclear,” and “Answer sounds plausible but doesn’t answer the question” can be grouped into evidence/citation failures, reasoning/synthesis failures, and format/requirement compliance failures. A failed tool call that the agent claims succeeded is a tool-result hallucination and should be treated as the core error. section 10.2.3 section 10.2
Figure 10.2 Workflow for defining agent evaluation criteria, from open coding to defining metrics
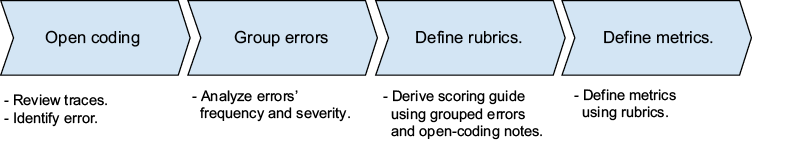
Use the workflow diagram to connect trace review, open coding, taxonomy construction, rubrics, and metrics. section 10.2
Table 10.3 Example of open coding result
| Input |
Agent output |
Tool trace |
Evaluation note |
|---|---|---|---|
| “Summarize paper X.” |
Plausible summary |
Tool call failed |
“Tool failed, but agent claims success.” |
Use the open-coding table to structure observations around inputs, outputs, tool traces, and evaluation notes. section 10.2.3
