Feature standardization transforms numerical features to zero mean and unit variance, preventing large-scale measurements from dominating model decisions. section 9.3.1
Apply standardization as a consistent training and prediction pipeline:
- Fit StandardScaler on the training feature vectors. section 9.3.1
- Transform the training vectors before fitting logistic regression. section 9.3.1
- Reuse the fitted scaler to transform test or prediction vectors. section 9.3.1
Node features on different scales
Node degree may range from 1 to 1,000 while centrality measures range from 0 to 1. Scaling both features prevents degree from overwhelming centrality in distance-based calculations. section 9.3.1
Figure 9.7 Training flow for node classification and link prediction. A critical step is the featurization of nodes and relationships. When this process is finished, the vectors can be passed to a classic algorithm. Both node classification and link prediction can be seen as classification tasks.
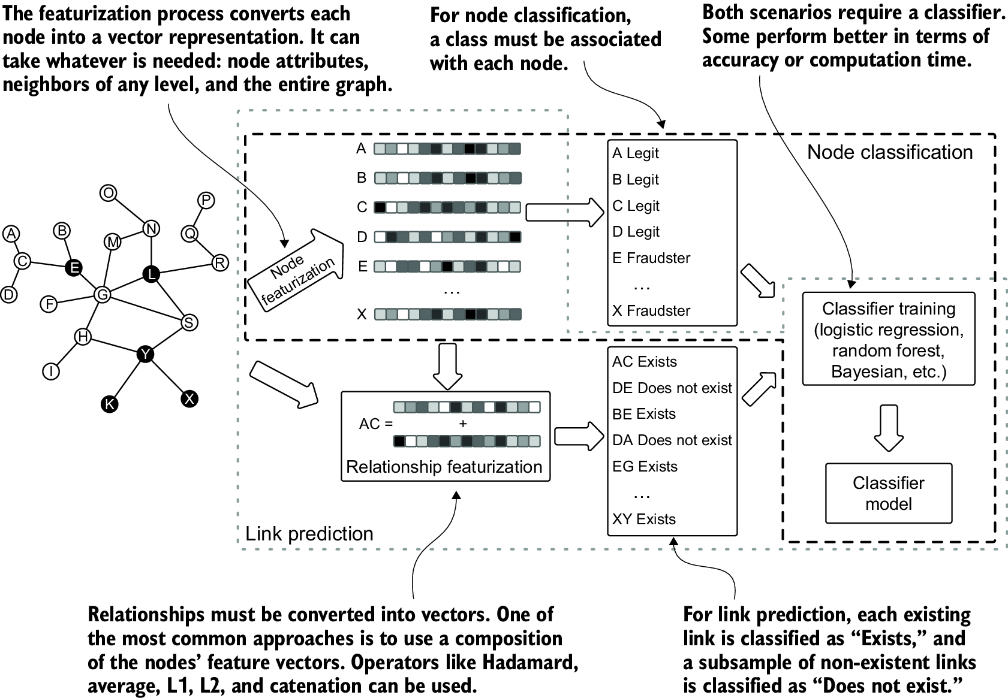
Use the training flow to locate standardization between node and relationship featurization and the downstream classifier. section 9.3.1




