A stateless operation processes each event independently. Its output depends only on the current input and transformation logic, not on previous events, retained state, lookups, or synchronization. This makes stateless processing lightweight and fast, but unsuitable when decisions require context across events. section 8.3.1
Common stateless operations include:
- Filtering events, such as passing through only orders worth at least 50 EUR. section 8.3.1
- Mapping events from one format to another, including simplifying an event’s output structure. section 8.3.1
- Flat-mapping one event into several events, such as splitting a CSV string into tokens. section 8.3.1
- Routing events by attributes or changing their keys to control distribution across output partitions. section 8.3.1
In an event-driven architecture, stateless transformations can sit in a processing layer between producers and consumers. For example, a service can read address-change events and publish billing and shipping variants to separate topics. Kafka Connect supports simple filtering and field renaming, while Kafka Streams and Apache Flink support broader processing pipelines. section 1.5.3 section 5.1.4
Event-triggered HTTP processing
An HTTP request can trigger an AWS Lambda function that processes the request, publishes the result to a Kafka topic, and then shuts down. This fits independent event handling, but cold starts and repeated consumer coordination can make serverless functions unsuitable for core Kafka consumption. section 12.2.2
Figure 12.3 Using Lambda functions to publish events. When an HTTP request is received, it triggers a Lambda function that processes the request and publishes the resulting data to a Kafka topic.
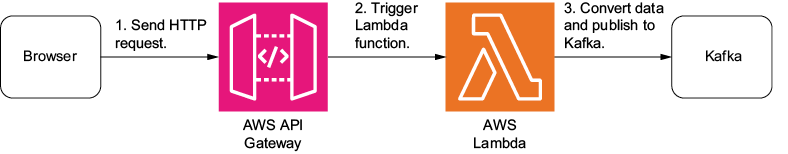
Shows an HTTP request triggering a Lambda function that processes data and publishes the result to Kafka. section 12.2.2













