A reduction needs synchronization when one thread consumes a partial result written by another. It ensures producers finish writing before consumers read, preventing incomplete values. section 4.0
The required coordination depends on where the cooperating threads run:
- Within a warp, lanes exchange values through register shuffles. section 4.1
- Across warps in a block, threads use shared memory and explicit barriers. section 4.1
- Across blocks, threads cannot synchronize within one kernel launch; coordination uses global memory, usually with another launch or atomics. section 4.1
Figure 4.2 The communication hierarchy for reductions on a GPU. Lanes within a warp exchange values through fast register shuffles. Warps within a block communicate through shared memory with explicit barriers. Blocks cannot synchronize inside a single kernel and must coordinate through global memory
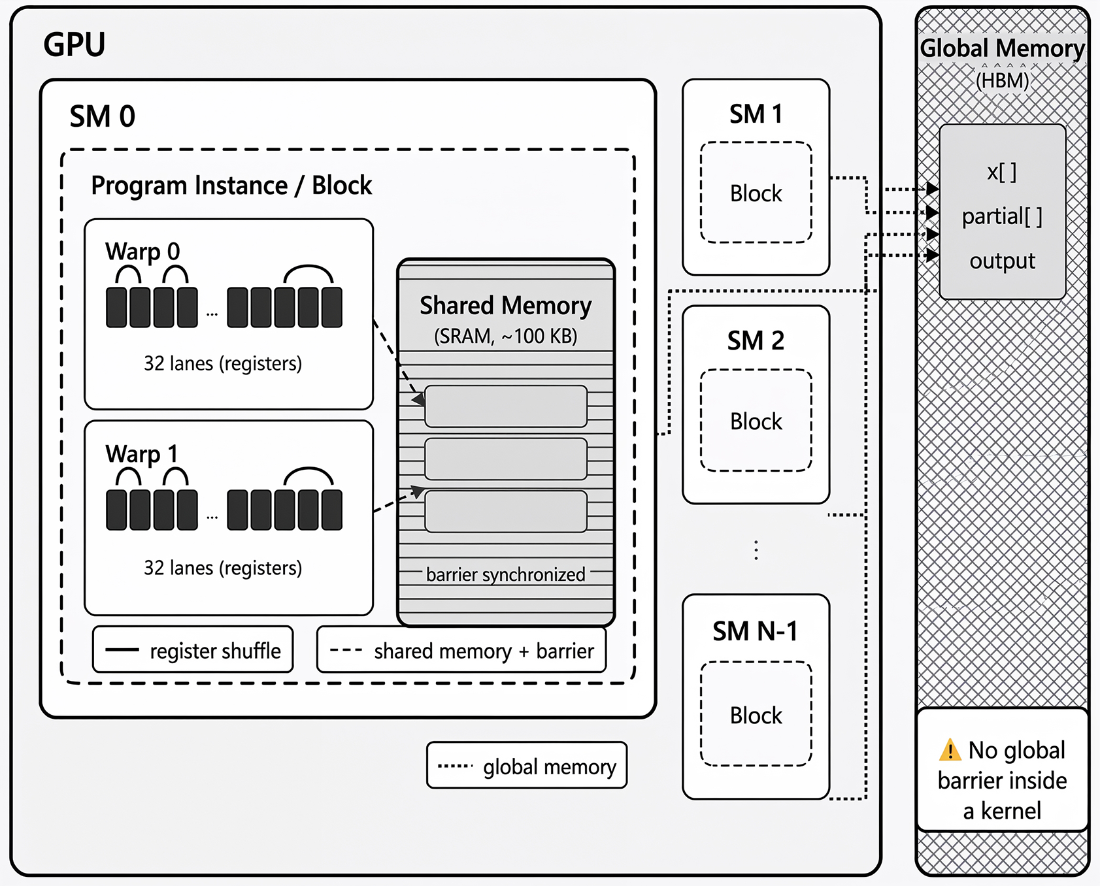
Shows how reduction communication and synchronization differ across GPU execution scopes. section 4.1












