A Taylor series approximates a smooth function near a chosen point using the function’s value and derivatives there. For a loss function, it describes how a parameter displacement changes the loss. The infinite expansion is exact only when all terms are included, but higher-order terms usually become negligible for small displacements. section 3.4 section 3.4.1
The approximation becomes progressively richer as terms are added:
- The first-order approximation keeps the gradient term and behaves like the tangent line; for very small displacements, it captures the main change. section 3.4.1 section 3.4.2
- The second-order approximation adds a quadratic displacement term governed by the Hessian matrix, improving accuracy for somewhat larger displacements. section 3.4 section 3.4.2
- In convex functions, a positive second derivative makes the quadratic approximation lie above or equal to the linear approximation locally. section 3.7.3
Exponential near zero
For the exponential function near x = 0, every derivative has value 1 at the expansion point. Its Taylor series therefore consists of terms whose successive powers of x become smaller near zero, making a short truncation useful. section 3.4.1
Equation 3.8
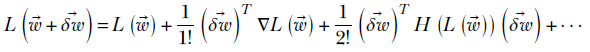
Use the multidimensional expansion figure to connect a parameter displacement with the gradient term and Hessian-based quadratic term. section 3.4.2
The expansion explains gradient descent: after dropping negligible quadratic and higher-order terms, the largest local decrease occurs along the negative gradient. The learning rate controls the step size; larger values move faster but may overshoot the minimum. section 8.4.3


