text-embedding-3-large converts words, sentences, and recipe sections into numerical vectors that a vector database can store and compare. The vectors represent textual meaning rather than merely matching identical words. section 14.6.1 section 14.10.1
A retrieval pipeline uses the model in two matching stages:
- Embed every stored recipe with text-embedding-3-large when populating the vector database. section 14.6.1
- Embed a user question with the same model, then search for nearby documents using cosine similarity. section 14.10.1
- Configure the model through an OpenAI API connection or an Azure deployment, selected by connection settings. section 14.6.1
Recipe retrieval
For a question such as “How can I make lasagna?”, the system creates a vector for the question and searches the recipe database. Cosine similarity prioritizes recipes whose vectors point in a similar direction, even when their wording differs. section 14.10.1
Figure 14.17 In the retrieval workflow, we can embed a user’s question and perform a similarity search in the database using cosine similarity. The vector database returns the documents that are most relevant to the question.
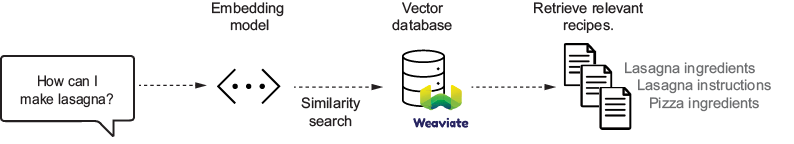
The retrieval workflow connects question embedding, cosine-similarity search, and the vector database’s returned documents. section 14.10.1
