An un-embedding matrix is a learned output projection that maps a hidden state into the model’s full vocabulary space, producing logits for token prediction. section 5.3.2
Within sequential multi-token prediction, the matrix:
- Receives the refined hidden state produced by an MTP module. section 5.3.2
- Produces a logits vector covering the complete vocabulary. section 5.3.2
- Is shared by the main model and all MTP heads. section 5.3.2
Sequential MTP prediction
After an MTP Transformer block creates a new hidden state, the shared un-embedding matrix converts it into vocabulary logits, from which the predicted future token is selected. section 5.3.2
Figure 5.12 The final prediction steps within an MTP module. The new hidden state generated by the MTP Transformer block is passed to a "Shared Un-Embedding Matrix." This projects the hidden state into the vocabulary space to produce a logits vector, from which the final token for that prediction step is selected.
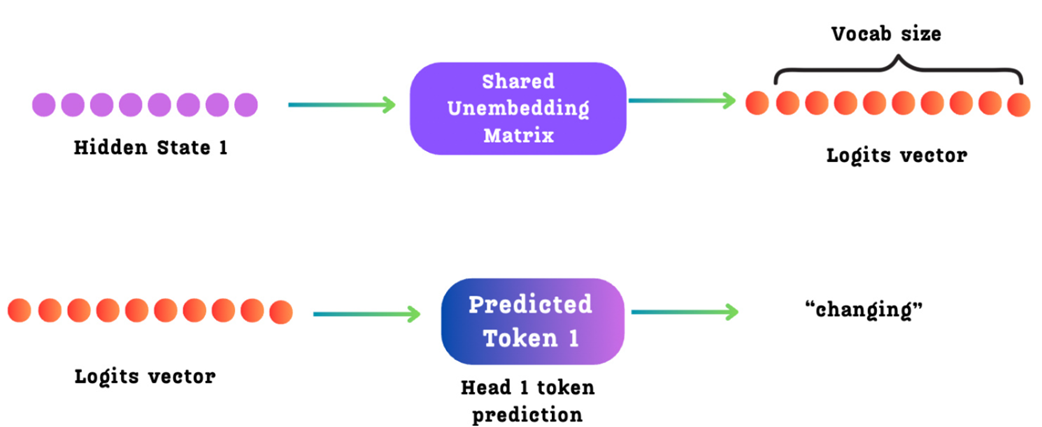
Trace the final prediction path from an MTP module’s hidden state through the shared projection to vocabulary logits and token selection. section 5.3.2
