A vision transformer (ViT) adapts transformer-based modeling from textual data to visual data. In fraud detection, it supports visual tasks such as extracting information from identity documents for automated know-your-customer (KYC) verification. section 4.4 section 4.3.4
Use vision transformers to:
- Process visual identity documents for automated KYC workflows. section 4.3.4
- Extend transformer-based attention modeling beyond text to visual fraud-detection data. section 4.4
Figure 4.19 Transformer model architecture containing multi-head attention layers that use attention mechanism only to extract complex information from input sequence.
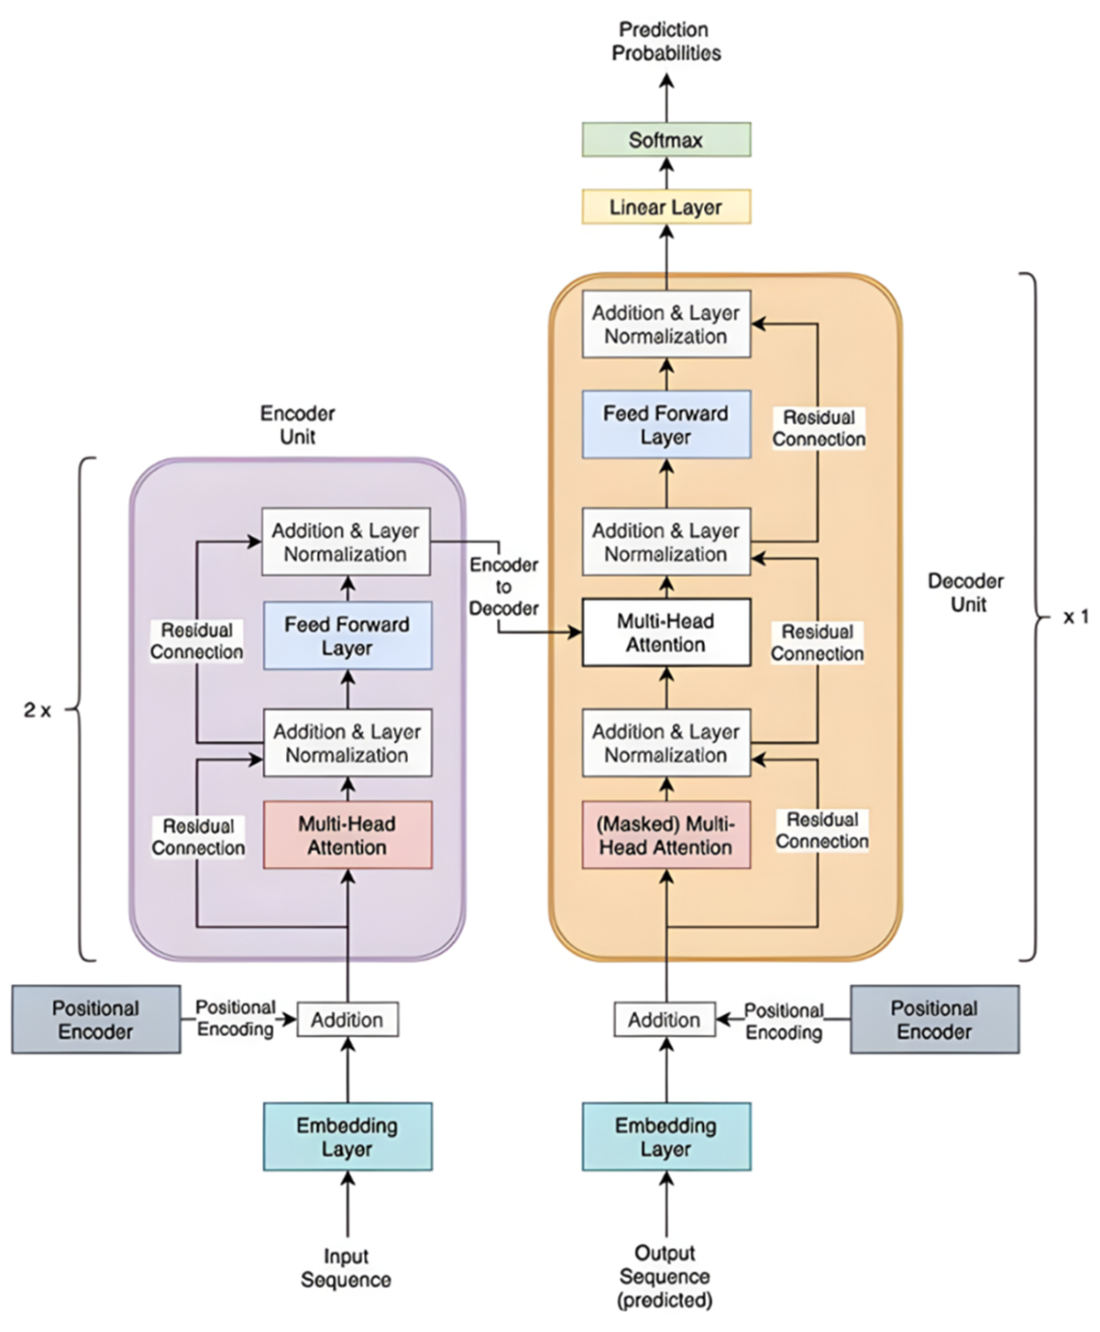
The transformer architecture figure provides context for the multi-head attention mechanism underlying the model family from which vision transformers emerged. section 4.3.4







