A web crawler is an automated program that visits web pages, reads their content, and follows links recursively to collect or index information across the internet. section 2.13 section 11.6
A crawler supports two closely related jobs:
- Index web pages and map relationships between pages, links, metadata, and content. section 2.13
- Collect large volumes of public text for language-model training, while accepting that the data will contain noise and spam. section 11.6
Following links across the web
Starting from a page, the crawler reads its information, visits linked pages, and repeats the process recursively. Google’s initial 1998 architecture used URL servers to feed search algorithms that crawled millions of pages and mapped the web’s structure. section 2.13
Figure 11.9 Sample training datasets and their domain compositions
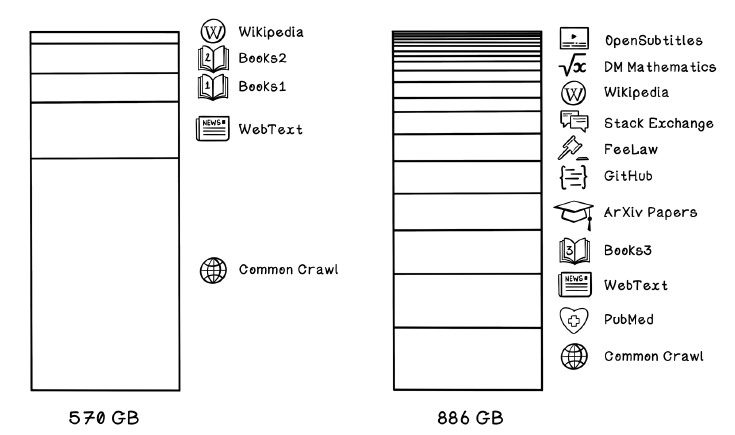
Use the dataset-composition figure to compare web-crawled text with other sources used to train language models. section 11.6

