Chunking divides documents into pieces for embedding and retrieval. The boundaries determine what a retrieval system can find: a chunk must contain enough context to answer a question without carrying so much unrelated text that its relevance is diluted. section 4.4.2
Keep a policy and its eligibility rules together
A policy states that California Family Rights Act (CFRA) leave is available to eligible employees, then specifies one year of employment and 1,250 hours worked in the preceding 12 months. Splitting those statements into separate 100–200-token chunks may retrieve the policy name but miss the eligibility rules. A chunk over 500 tokens may retain both yet also contain other policies, weakening its relevance to an eligibility question. section 4.4.2
Figure 4.6 Small chunks (top) may separate related information, causing retrieval to miss crucial context when answering specific queries. Large chunks (bottom) keep related information together but may have diluted relevance scores because they include unrelated content. This fundamental tradeoff significantly affects your RAG system’s ability to find and retrieve appropriate information.
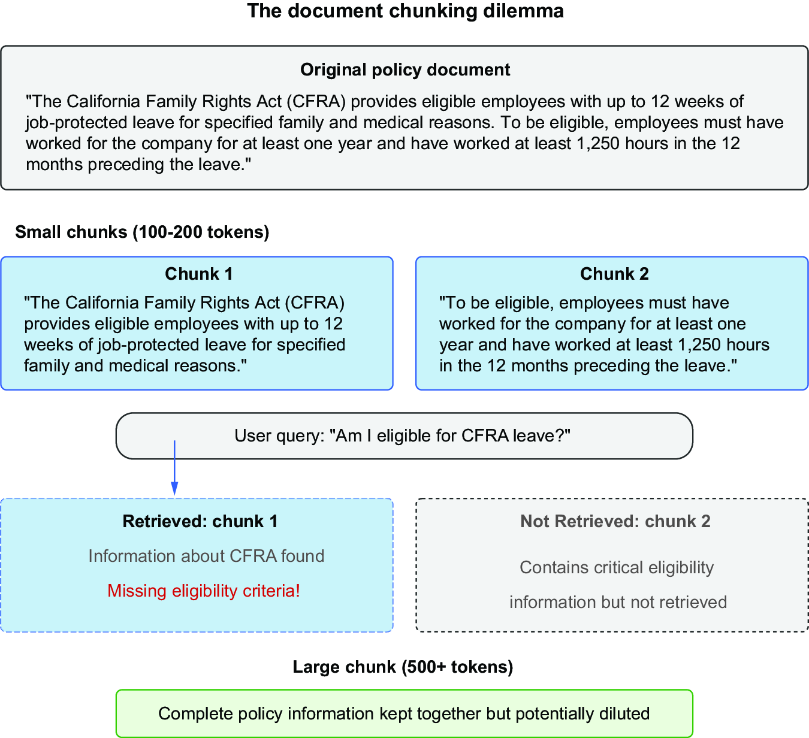
Compare the two boundary failures: missing related context in small chunks and diluted relevance in large ones. section 4.4.2
Choose boundaries that fit the document type:
- For legal documents, detect section headers or numbered clauses so a complete legal concept stays intact. section 4.4.2
- For narrative prose, split on paragraph breaks while enforcing a minimum length to avoid fragments. section 4.4.2
- For code documentation, preserve fenced code blocks and function signatures alongside their explanations. section 4.4.2
- When no specialized parser applies, use overlapping sliding windows; the illustrated fallback uses a chunk size of 500 and overlap of 100. section 4.4.2
def chunk_document(document, content_type):
    """Apply different chunking strategies based on content type"""
    if content_type == "legal":    #1
        return chunk_by_section(document)   #1
    elif content_type == "narrative":    #2
        return chunk_by_paragraph(document, min_length=200)   #2
    elif content_type == "code_documentation":    #3
        return chunk_preserving_code_blocks(document)   #3
    else:
        return sliding_window_chunks(document,
        chunk_size=500, overlap=100)   #4
A Python-style dispatcher selects a chunker by content type and reserves overlapping windows for the fallback case. section 4.4.2
A simple sliding-window implementation splits text on whitespace and advances by chunk size minus overlap. That makes the overlap explicit, but it does not preserve document structure by itself. Label resulting chunks with metadata such as section headings, page numbers, filenames, and publication dates so retrieval can use their source context. section 4.4.2 section 4.7
def sliding_window_chunks(text, chunk_size=500, overlap=100):
    """Create overlapping chunks using a sliding window"""
    tokens = text.split()
    chunks = []

    for i in range(0, len(tokens), chunk_size - overlap):
        chunk = tokens[i:i + chunk_size]    #1
        if chunk:    #2
            chunks.append(" ".join(chunk))

    return chunks
Inspect the window loop and its step size when implementing the overlapping fallback. section 4.4.2




