liveBook · Manning

Alert fatigue

As explained in Cloud Observability in Action

Alert fatigue is the reduced ability to notice or appropriately respond to important alerts because of excessive notifications.

Alert fatigue is the reduced ability to notice or appropriately respond to important alerts when excessive notifications compete for attention. In cloud operations, the goal is to notify humans about events that affect the system without overwhelming them. section 7.2.1 section 7.4

Prometheus evaluates alerting rules and sends firing alerts to Alertmanager. Alertmanager then deduplicates, groups, filters, and suppresses notifications before routing concise messages to destinations such as email, Slack, text messages, or webhooks. This separation helps reduce alert storms while allowing either component to scale or restart independently. section 7.2.1

Reducing notifications for a Kubernetes cluster

Suppose an operator manages a Kubernetes cluster with multiple namespaces. Instead of forwarding every firing alert separately, Alertmanager can group related alerts, suppress duplicates, and apply time-based routing—for example, Slack during work hours and text messages afterward. A Docker Compose setup can connect Prometheus, Alertmanager, and a webhook receiver to exercise this flow. section 7.2.1
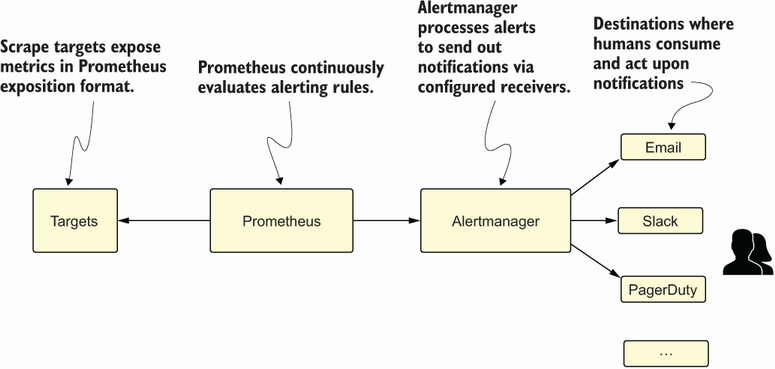
Figure 7.2 Prometheus and the Alertmanager

Use the architecture diagram to trace metrics from scraped targets through Prometheus and Alertmanager to the operator-facing notification. section 7.2.1


How Cloud Observability in Action covers it

How deep it goes
Explains notification routing, deduplication, grouping, and suppression, but stops short of defining a universal threshold for acceptable alert volume.
Examples
Uses a multi-namespace Kubernetes cluster, time-based Slack and text routing, grouped alerts, and a Docker Compose webhook setup.
What it assumes
Assumes basic familiarity with monitoring and alerts while introducing Prometheus evaluation and Alertmanager processing roles.
What you can do after
Operate/configure Prometheus and Alertmanager to route fewer, more concise notifications to human operators.
How it connects
Connects alert fatigue with Prometheus, Alertmanager, alerting rules, alert storms, monitoring, and incident response.

Also explained in

Compare how 3 books explain alert fatigue →

Related concepts

This explainer was generated by Manning's knowledge graph from the text of Cloud Observability in Action. The section links point to the parts of the book it draws on.
