All-to-all communication exchanges tokens between experts located on different GPUs. In mixture-of-experts training, this shuffle can become more expensive than the pipeline bubble and leave GPUs waiting for data. section 6.5.4
Treat the operation as a scheduling problem rather than an isolated transfer:
- 1F1B scheduling alone cannot prevent GPUs from idling while MoE tokens move between experts. section 6.5.4
- DualPipe decomposes forward and backward work into attention, expert MLP, and all-to-all communication. section 6.5.6
- DualPipe overlaps communication for one micro-batch with attention, expert computation, or backward work for another. section 6.5.6
Hiding the transfer
While one micro-batch performs an all-to-all exchange, another executes an expert or attention operation. The GPU’s compute cores and networking hardware then work in parallel instead of waiting sequentially. section 6.5.6
Figure 6.8 The DualPipe schedule with fine-grained overlap. This diagram shows how forward, backward, and overlapped tasks are scheduled to keep the GPUs constantly busy and hide communication latency.
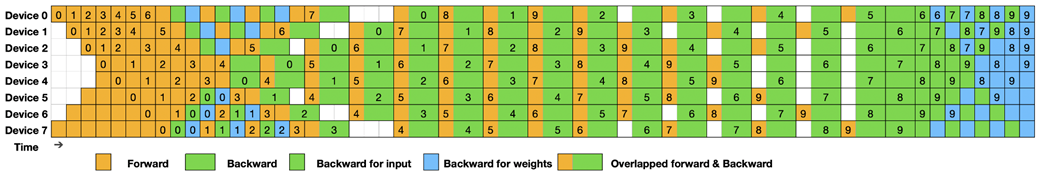
Use the DualPipe timeline to trace how forward, backward, expert, attention, and all-to-all tasks are arranged to keep GPUs busy. section 6.5.6
