A data warehouse is a centralized analytics system that extracts data from OLTP systems, transforms it into optimized schemas, and supports OLAP workloads. It addresses the poor fit between transactional databases and large-scale historical analysis, but traditionally trades flexibility for performance, governance, cost, and rigidity. section 1.2 section 1.0
Architecture and operational tradeoffs include:
- Separates analytical workloads from OLTP systems so large scans and aggregations do not slow transaction processing. section 1.2
- Centralizes transformed historical data in warehouse-specific schemas optimized for reporting and analytical queries. section 1.2
- Provides strong performance and governance, while traditional systems remain expensive, rigid, and difficult to change. section 1.0
- Improves flexibility in cloud deployments by separating storage from compute, but still requires loading data before analysis and can create vendor lock-in. section 1.3
Cloud warehouse deployment
Snowflake, Google BigQuery, and Amazon Redshift let organizations scale query processing independently from retained data and pay for usage rather than provisioning all capacity up front. However, copying operational data into warehouses can add latency, duplicated storage, and pipeline complexity. section 1.3
Figure 1.1 The evolution of data platforms (data warehouse or data lake to data lakehouse) and deployment models (on-premises to cloud)
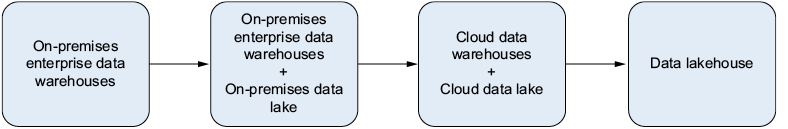
Trace the progression from on-premises data warehouses and data lakes to cloud data lakehouses. section 1.1



