A computation graph maps the operations in a computation and how data flows between them. Like a flowchart, it shows how inputs pass through operations to produce outputs. In PyTorch, these graphs help with both automatic differentiation and model export. section 5.5.1 section 17.2.2
When a loss is computed from parameters that require gradients, PyTorch records the operations in an autograd computation graph. Calling loss.backward() traverses the graph in reverse to calculate derivatives of the loss with respect to those parameters. section 5.5.1
Gradients for a simple model
For a model that predicts w * t_u + b, set params = torch.tensor([1.0, 0.0], requires_grad=True). Then compute loss = loss_fn(model(t_u, *params), t_c) and call loss.backward(). The derivatives for w and b are available in params.grad. section 5.5.1
Figure 5.10 The forward graph and backward graph of the model as computed with autograd.
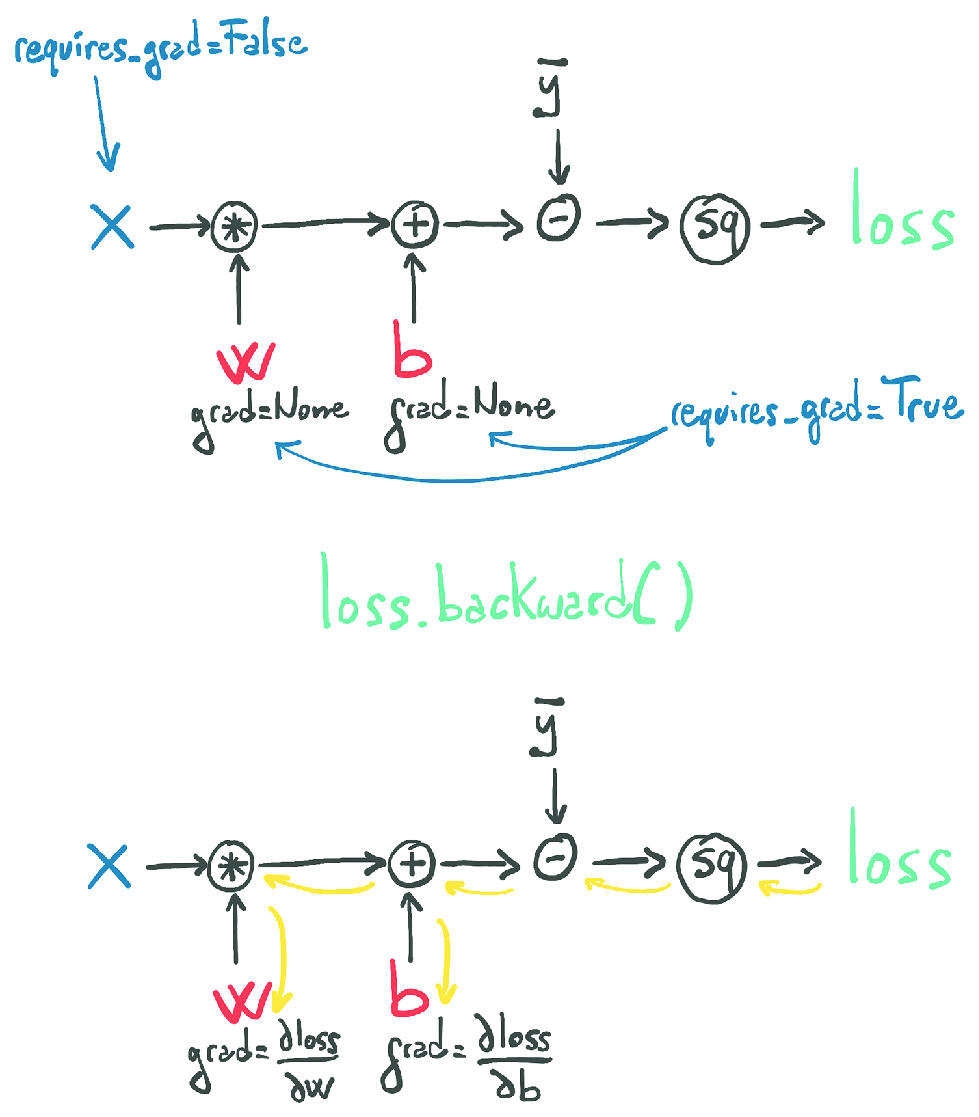
Compare the forward operations with the reverse traversal used to compute gradients. section 5.5.1
Gradients accumulate at leaf tensors: calling backward again adds to the existing values rather than replacing them. In a training loop, zero the gradients explicitly before the next iteration, for example with params.grad.zero_() when params.grad is not None. section 5.5.1
A graph can also represent a model for deployment. torch.export takes a torch.nn.Module and an example input to produce a traced graph describing the model’s operations and data flow. This is a deployment-oriented representation, distinct from the autograd graph used to compute gradients. section 5.5.1 section 17.2.2
Listing 17.9 Examining exported program graph representation
# In[]
print(exported_program)

# Out[]
ExportedProgram:
  class GraphModule(torch.nn.Module):
    def forward(self, p_fc1_weight: "f32[5, 10]", p_fc1_bias: "f32[5]",
     p_fc2_weight: "f32[2, 5]", p_fc2_bias: "f32[2]", x: "f32[2, 10]"):
      # File: .py:10 in forward, code: x = self.fc1(x)
      linear: "f32[2, 5]" = torch.ops.aten.linear.default(x, p_fc1_weight, p_fc1_bias);
       x = p_fc1_weight = p_fc1_bias = None

      # File: .py:11 in forward, code: x = self.relu(x)
      relu: "f32[2, 5]" = torch.ops.aten.relu.default(linear);  linear = None

      # File: .py:12 in forward, code: x = self.fc2(x)
      linear_1: "f32[2, 2]" = torch.ops.aten.linear.default(relu, p_fc2_weight, p_fc2_bias);
       relu = p_fc2_weight = p_fc2_bias = None
      return (linear_1,)
Inspect an exported graph in which data flows through a linear operation, ReLU, and a second linear operation. section 17.2.2







