Compute is the processing capacity needed to train and run AI models. It is distinct from computation, the operations a machine performs: compute concerns the capacity available to carry them out. For large models, that capacity shapes what can be built and deployed. section 8.1.2 section 1.3.2 section 4.7.2
Modern AI workloads involve many numerical operations that can be performed in parallel. GPUs, originally designed for graphics, are well suited to this work. More specialized accelerators, including TPUs and AWS Trainium and Inferentia, can be more efficient for particular tasks but offer less flexibility and depend on controlled software environments. section 8.1.2
Compute is only one part of the infrastructure needed at scale. Frontier training also relies on specialized hardware, high-bandwidth networking, and a reliable energy supply over long periods. Together, these resources constrain model size, training duration, and the amount of failure an organization can absorb. section 4.7.2
More compute does not by itself explain progress in AI. Advances in data availability and training methods also made large-scale learning practical. Conversely, fluent behavior is not, on its own, evidence of understanding or awareness. section 1.4.3 section 1.5.8
Access is shaped by an industrial supply chain, not just a technical specification. Chip manufacturing depends on concentrated capacity and critical inputs, while demand for high-end GPUs can exceed supply. Organizations may secure capacity through partnerships that also tie model development and deployment to particular cloud platforms. Software optimized for specific hardware can improve performance while making workloads harder to move. section 8.1.2 section 8.1.3
Figure 8.1 The large language model ecosystem. Models are built on a layered system that begins with specialized hardware and extends through cloud infrastructure and model providers. Interaction with this system occurs primarily through the two bottom layers, where users either consume models via managed services that abstract the underlying complexity or deploy open-weight models on self-managed infrastructure, taking on greater control and responsibility.
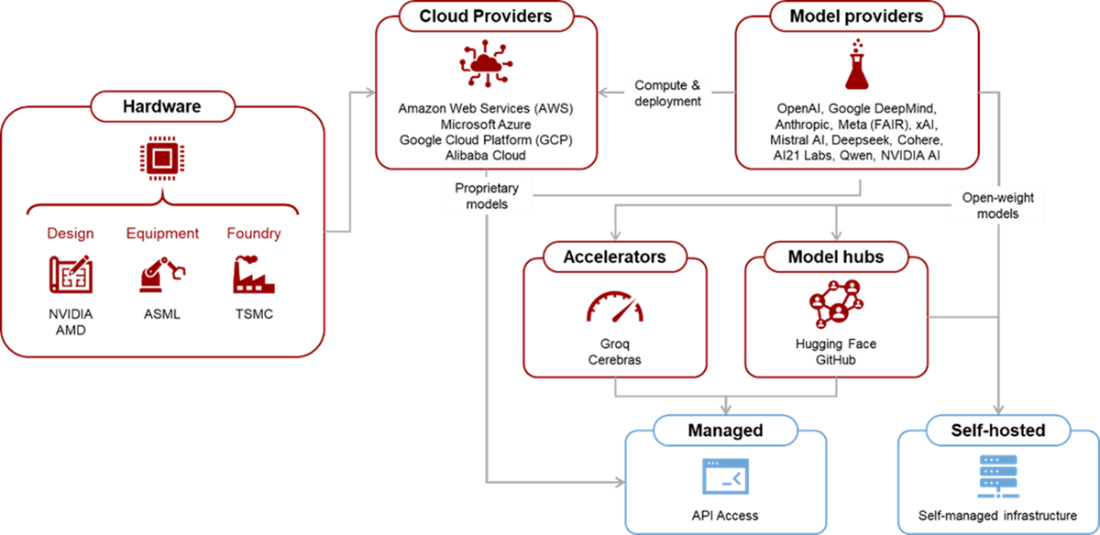
Places compute in the broader model ecosystem, from specialized hardware through cloud infrastructure to deployment. section 8.1.2



