Data ingestion acquires data from streams, files, databases, and separate infrastructures, then brings it into a target system for ML processing or storage. section 5.4
Plan ingestion around these delivery decisions:
- Select sources such as RabbitMQ, Kafka, XLSX, CSV, Parquet, SQL tables, cloud services, SaaS applications, or on-premises stores. section 5.4
- Choose the target infrastructure and data engines, balancing convenient cloud processing against security requirements that may keep sensitive data on premises. section 5.4
- Preserve usable downstream forms by creating intermediate tables or data stores before cleaning data and engineering features. section 5.4
Figure 5.1 The processing requirements delivered using the dev environment data pipeline infrastructure. This provides the data resources for the ML modeling team in sprint 2 and beyond.
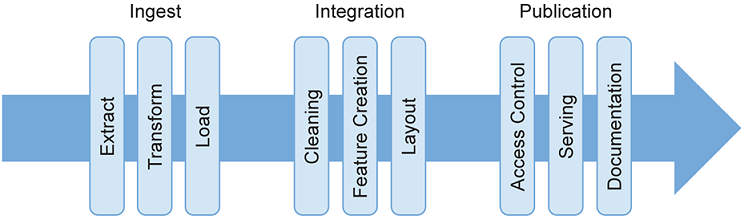
Use the pipeline overview to connect ingestion with the processing resources delivered for ML modeling. section 5.4





